04 / Build journals

Stories from the build.

What was hard, what broke, what survived the cut, one post per project. Sorted by the recency of the work, not the day I wrote it down.

Scores typed courtside, on the website before the next game starts
Sep. 2026 - Present
9 min read

Scores typed courtside, on the website before the next game starts

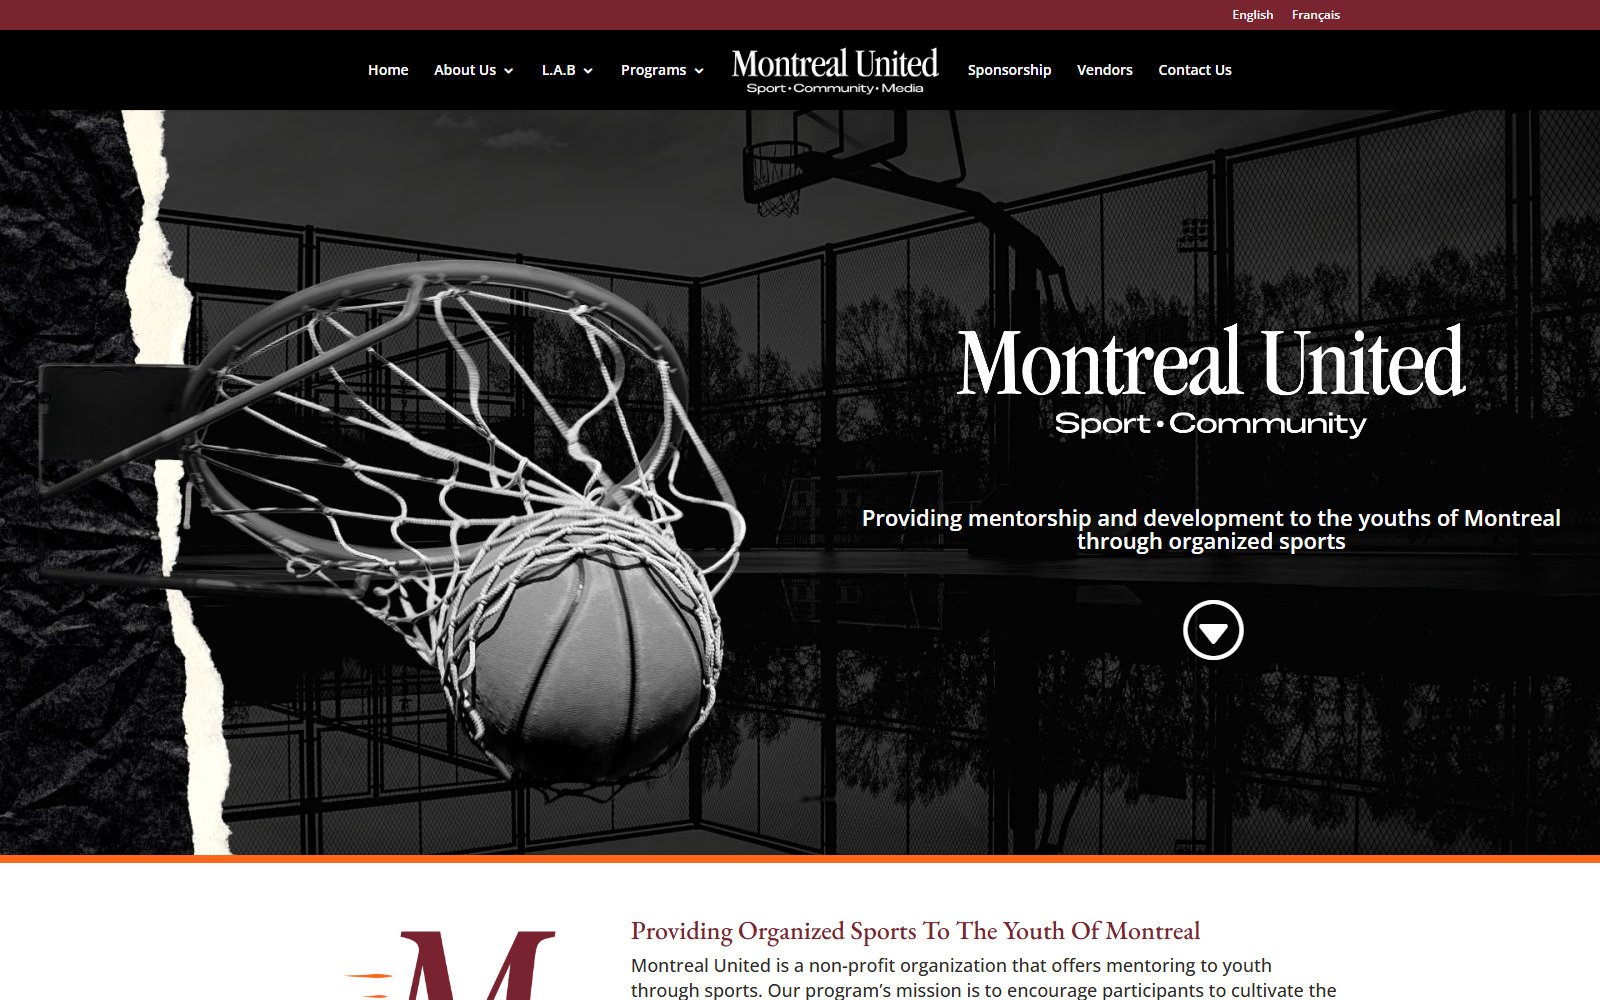
Montreal United runs mentorship and organised sports for youth in Montreal, including two annual basketball tournaments. I took over their bilingual WordPress site in September 2026 and built them a second thing they asked for: a way to run a tournament from a phone at the gym. Divisions, pools, generated games and scores go in on the phone, and the public page picks them up on its own, in English and French. The part I spent the most care on is the part that refuses, because the person using it is standing at a scorer's table with a game finishing behind them.

WordPressDiviWPML
An agent that will not put words in Canon's mouth: 21 of 22 quotes found word for word in the manufacturer's own documents
Sep. 2026
10 min read

An agent that will not put words in Canon's mouth: 21 of 22 quotes found word for word in the manufacturer's own documents

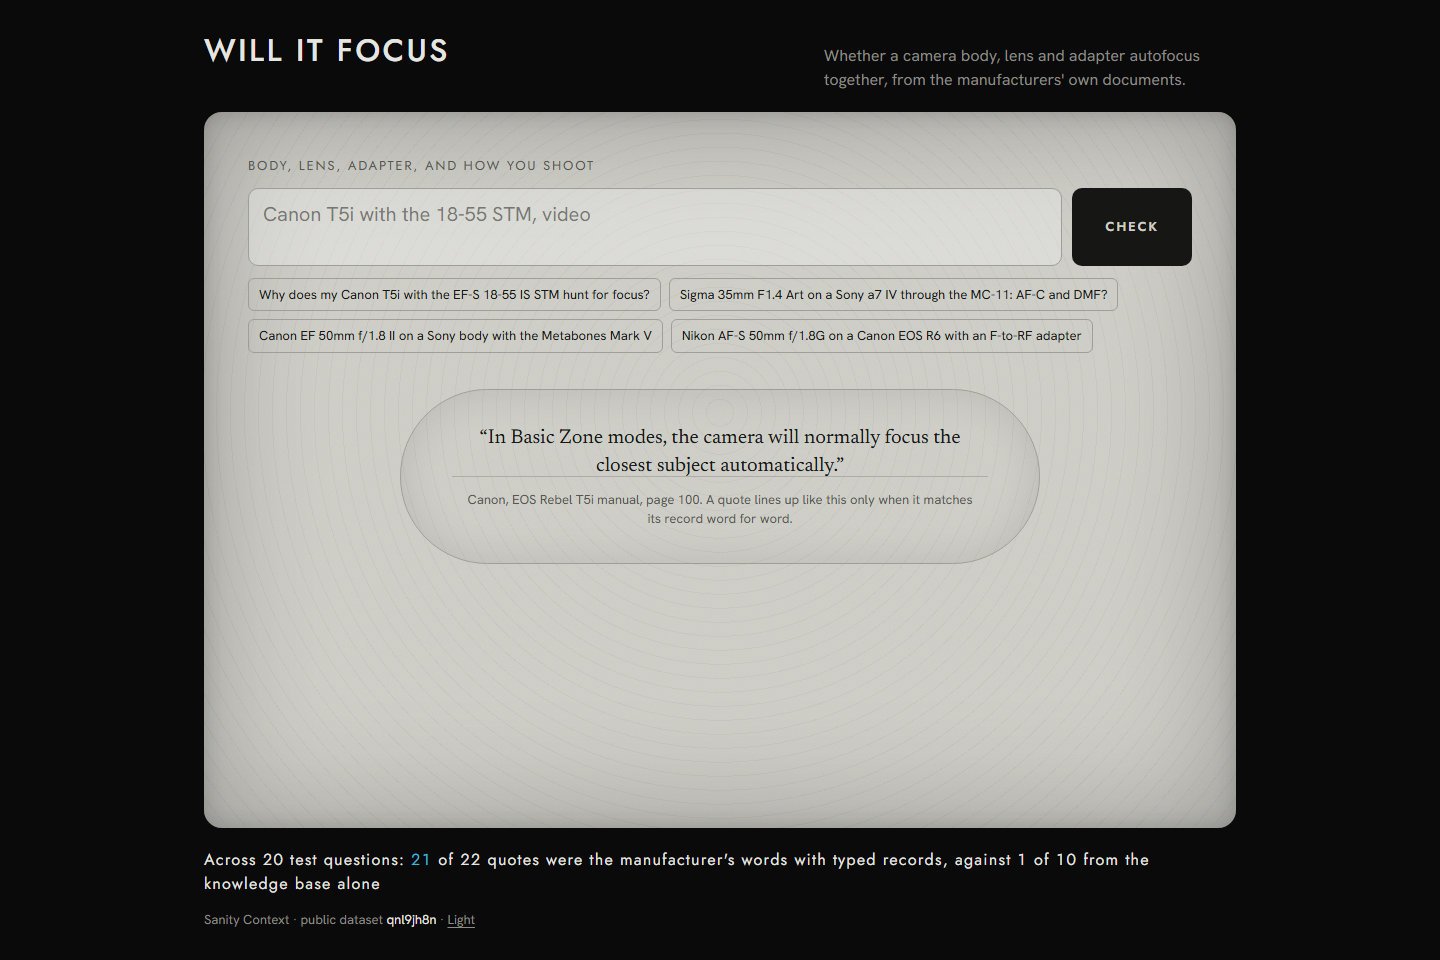
When I worked in film, my Canon T5i would miss focus in auto mode and I would switch to manual. Canon's manual explains it on page 100, and I never read it. Compatibility questions like that have published answers that are hard to find and easy to misquote, so Will It Focus reads the manufacturers' own documents and refuses to paraphrase them into quotation marks. Two Sanity Context endpoints, one agent on gpt-5.4-mini: 131 typed records serve the verdicts, a Knowledge Base built from six manufacturer PDFs serves the explanations, and after the model answers, code looks up every quote in the record it cited. Over 20 questions graded by Sigma's, Canon's and Metabones' own tables, 21 of 22 quoted passages are word for word. The first time I ran it on the Knowledge Base alone it put quotation marks around 13 sentences that appear in none of the six documents, which is the whole reason the verbatim text now lives in typed records.

Sanity ChallengeSanity ContextMCP
The couch that would not go down the stairs, and the phone that now says so before you buy it
Sep. 2026
11 min read

The couch that would not go down the stairs, and the phone that now says so before you buy it

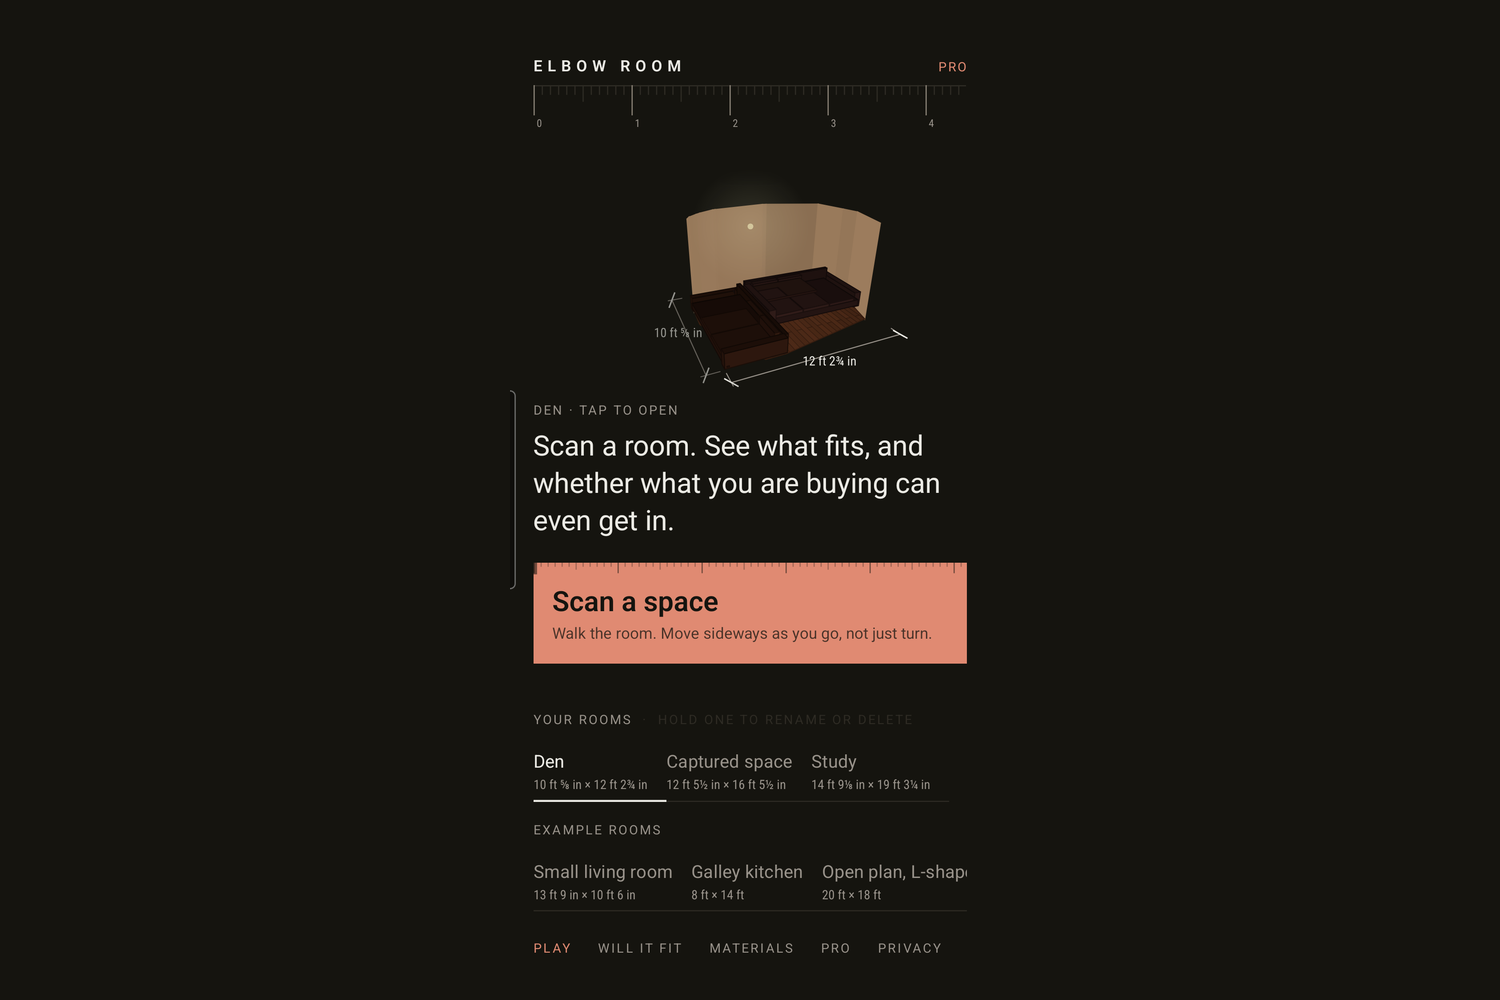
I bought a couch that would not go down my basement stairs. The flight turns ninety degrees on three winder treads, and I found out halfway, with the couch wedged and the wall gouged. Then a flood forced a water heater replacement and two installers brought a 279 litre tank down the same stairs. Two objects, one staircase, nobody measured it either time. Elbow Room Mobile scans a room with an Android phone that has no LiDAR, gives it back as a 3D model you can design, furnish and walk as your Sim, and answers the question no furniture app answers: can the thing actually get in. A three-seat sofa in the example house clears the front door and the hallway, then loses by 2 ft 10 in at the turn. The solver behind that is checked against the published closed form for a zero-width rod, which is the one part of the receipt I did not write the answer to.

RevenueCat ShipatonRevenueCatReact Native
Sixteen real calls to pharmacies, zero prices, and the measured reason why: the agent talks over the pharmacist
Sep. 2026
10 min read

Sixteen real calls to pharmacies, zero prices, and the measured reason why: the agent talks over the pharmacist

Pharmacies paid about 43 cents for thirty metformin, a number CMS publishes weekly from invoices. What you pay is different at every counter and published nowhere, so the only way to learn it is to phone. Sticker gives a CALL-E phone agent a drug and a ZIP, reads the federal NPI registry, calls the pharmacies you authorize, and joins every quoted price to CMS NADAC. Sixteen real calls in one Manhattan ZIP produced zero prices and zero refusals. The platform's own event stream showed why: 24 collisions across 15 traced calls where the agent opened its turn while the pharmacist was still speaking. Filed upstream as issue #415, picked up by a maintainer the same day. The contribution merged as PR #404 after five review passes. Zero is a result if you say how you got it.

CALL-EPhone agentsCMS NADAC
An insurer upholds its own denial two times in three. An independent doctor overturns it three times in four. Day Thirty is the appeal nobody files
Sep. 2026
11 min read

An insurer upholds its own denial two times in three. An independent doctor overturns it three times in four. Day Thirty is the appeal nobody files

Insurers upheld 66 percent of appeals they received in 2024 (KFF). California's Independent Medical Review overturned 72.3 percent of the denials that reached an independent physician in 2025. Under one percent of denials get appealed at all, partly because of a clock nobody explains: thirty days after you file a grievance, whether or not the plan has answered, a six-month deadline starts. Day Thirty reads the denial with Nova, computes the deadline from the statute with every provision cited, pulls how California actually decided 22,090 comparable cases, drafts the appeal with Haiku 4.5, and stops at a Strands interrupt for your signature. 15.1 seconds median to a drafted appeal at the gate. Every number graded by the state's own record.

AgentsForHumansAmazon BedrockStrands Agents
Your Canadian truck already drove that lane empty. Northbound finds the freight it could legally have carried
Sep. 2026
10 min read

Your Canadian truck already drove that lane empty. Northbound finds the freight it could legally have carried

10,479 completed legs, 1,596,093 miles, two months of Roadstar Trucking's real dispatch data. Coming home empty happened six times. The real empty running is inside the United States, between loads, and whether it could have carried freight turns out to be a legal question, not a routing one. 19 CFR 123.14(c)(1) permits US point-to-point carriage when it is part of the return of the vehicle to its base country, so the verdict turns on which way the load runs. 217 legs, 66,702 miles, $155,815 at ATRI's 2025 industry cost, already travelling toward the border and legally able to carry. GLM 5.2 on SPUR reads the offer, a deterministic TypeScript engine cites the statute. Ablation on 100 real offers in five broker formats: 100 percent correct verdict with the model, 40 percent without.

RoadStarHackathonGLM 5.2SPUR Compute
A camera assistant wears smart glasses through a shoot and walks off set with the continuity paperwork already written
Sep. 2026
10 min read

A camera assistant wears smart glasses through a shoot and walks off set with the continuity paperwork already written

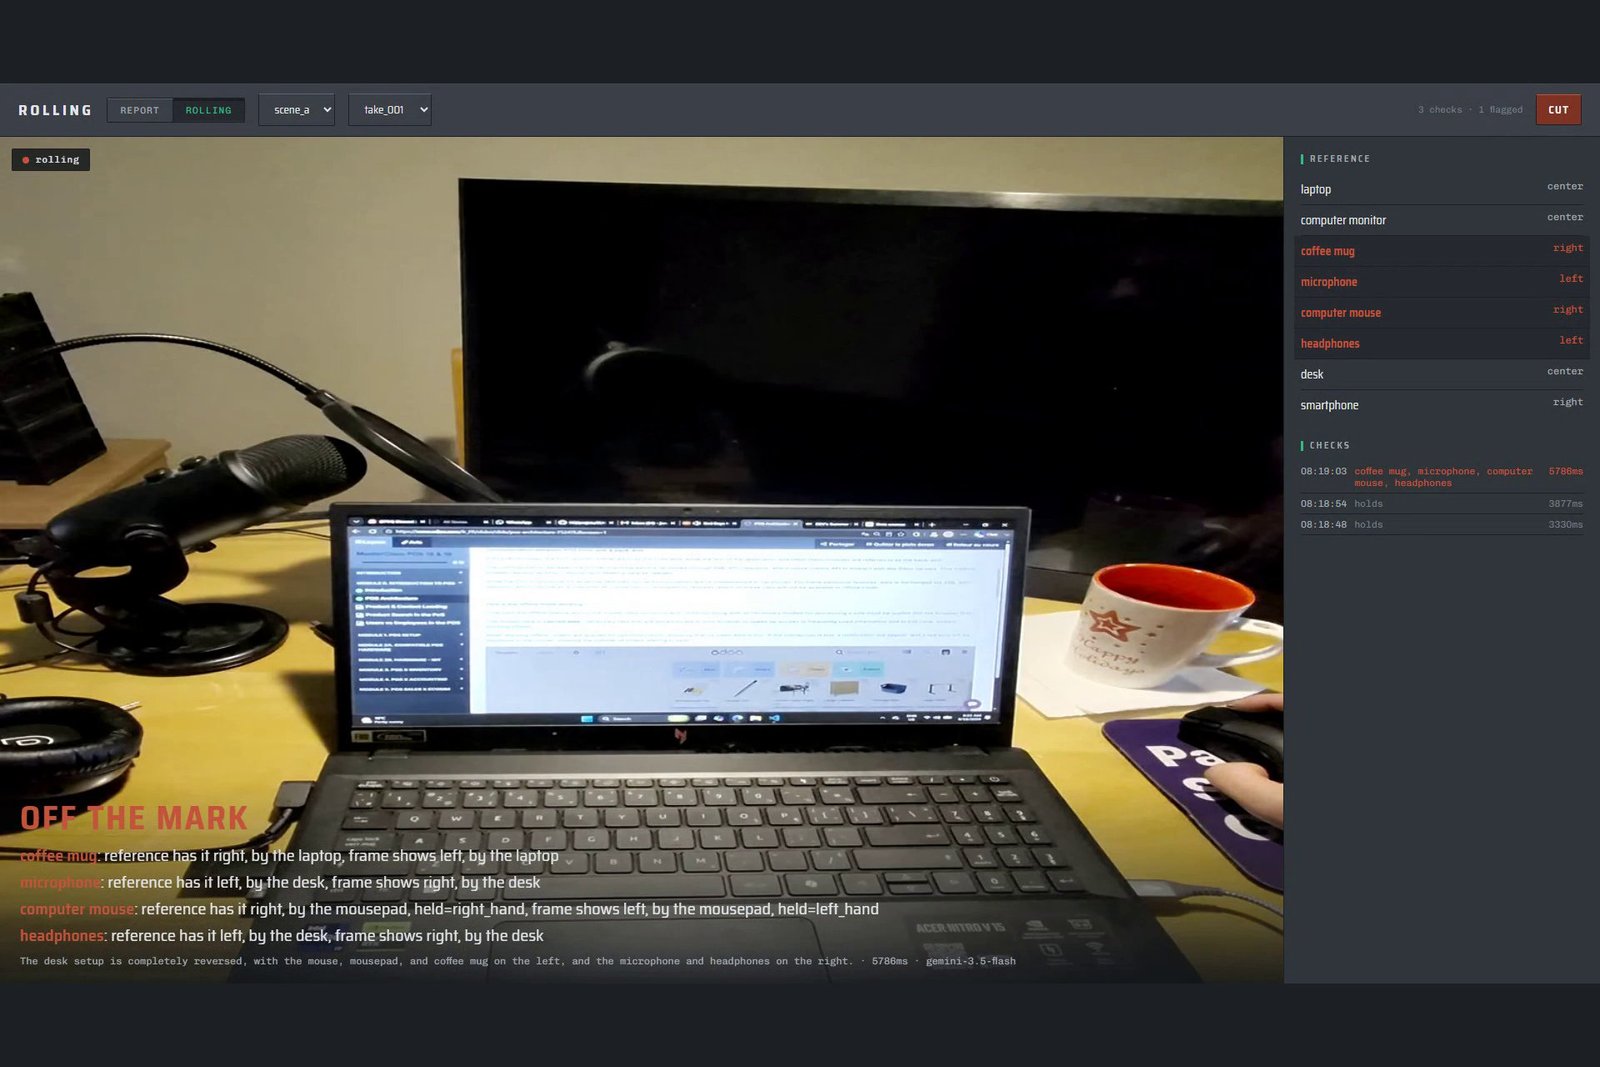
The last job on a film shoot still done entirely on paper is continuity. Miss a line, find out at the edit, pay for a pickup day at $1,440 to $3,020 (Giggster 2026). Dailies watches a take through Ray-Ban Meta Gen 2 glasses for 1.6 cents at Google's published Gemini rates, 63 cents a forty-take day, 0.04% of the day it is guarding. Gemini reads every take, ClickHouse Cloud holds the observations, and a plain-English question box lets an agent write its own SQL through the official mcp-clickhouse server. The agent cannot destroy data: three independent layers, and the one that matters is a readonly cluster credential refusing DROP, INSERT, TRUNCATE, CREATE TABLE and ALTER with ClickHouse code 497. Median rolling verdict is 4.4 seconds, spoken back into the wearer's ear. The catch in the 2 min 31 s demo lands at 0:49.

AgenticCinemaClickHouseRay-Ban Meta
The couch took some of my basement wall on the way out. I built the planner nobody sold me
Sep. 2026
9 min read

The couch took some of my basement wall on the way out. I built the planner nobody sold me

Every room planner ever built answers does it fit in the room. Elbow Room answers the question that costs people money and plaster: can it even get there. Predicted two real outcomes at my own house that had already happened (a couch that did not fit, a 279 litre water heater that did), agrees to 1.63 x 10^-6 inches with a 300-year-old closed-form corner solve, and ships 19 WebMCP tools so an agent can operate the canvas by talking. Cross-origin bonus: a separate furniture shop can ask my staircase over a shared read-only tool, both sides consent by name.

WebMCPModel Context ProtocolCanvas
I just published my first Udemy course: the ServiceNow catalog build I've done twenty times, plus the Now Assist Skill Kit end to end
Sep. 2026
4 min read

I just published my first Udemy course: the ServiceNow catalog build I've done twenty times, plus the Now Assist Skill Kit end to end

Two years on the ServiceNow team at Cirque du Soleil, plus a stretch on client work at N2, taught me which parts of the catalog + Flow Designer + Now Assist stack you actually reach for and which parts the docs make you think matter but don't. The course is that filter, recorded from scratch on a fresh instance, ending with a Now Assist Skill Kit publish flow that isn't in the docs yet. Launch coupon inside.

ServiceNowFlow DesignerNow Assist
Nightshift reads 2,000 patents in 4 minutes for $34 and finds the reference the examiner missed
Aug. 2026
11 min read

Nightshift reads 2,000 patents in 4 minutes for $34 and finds the reference the examiner missed

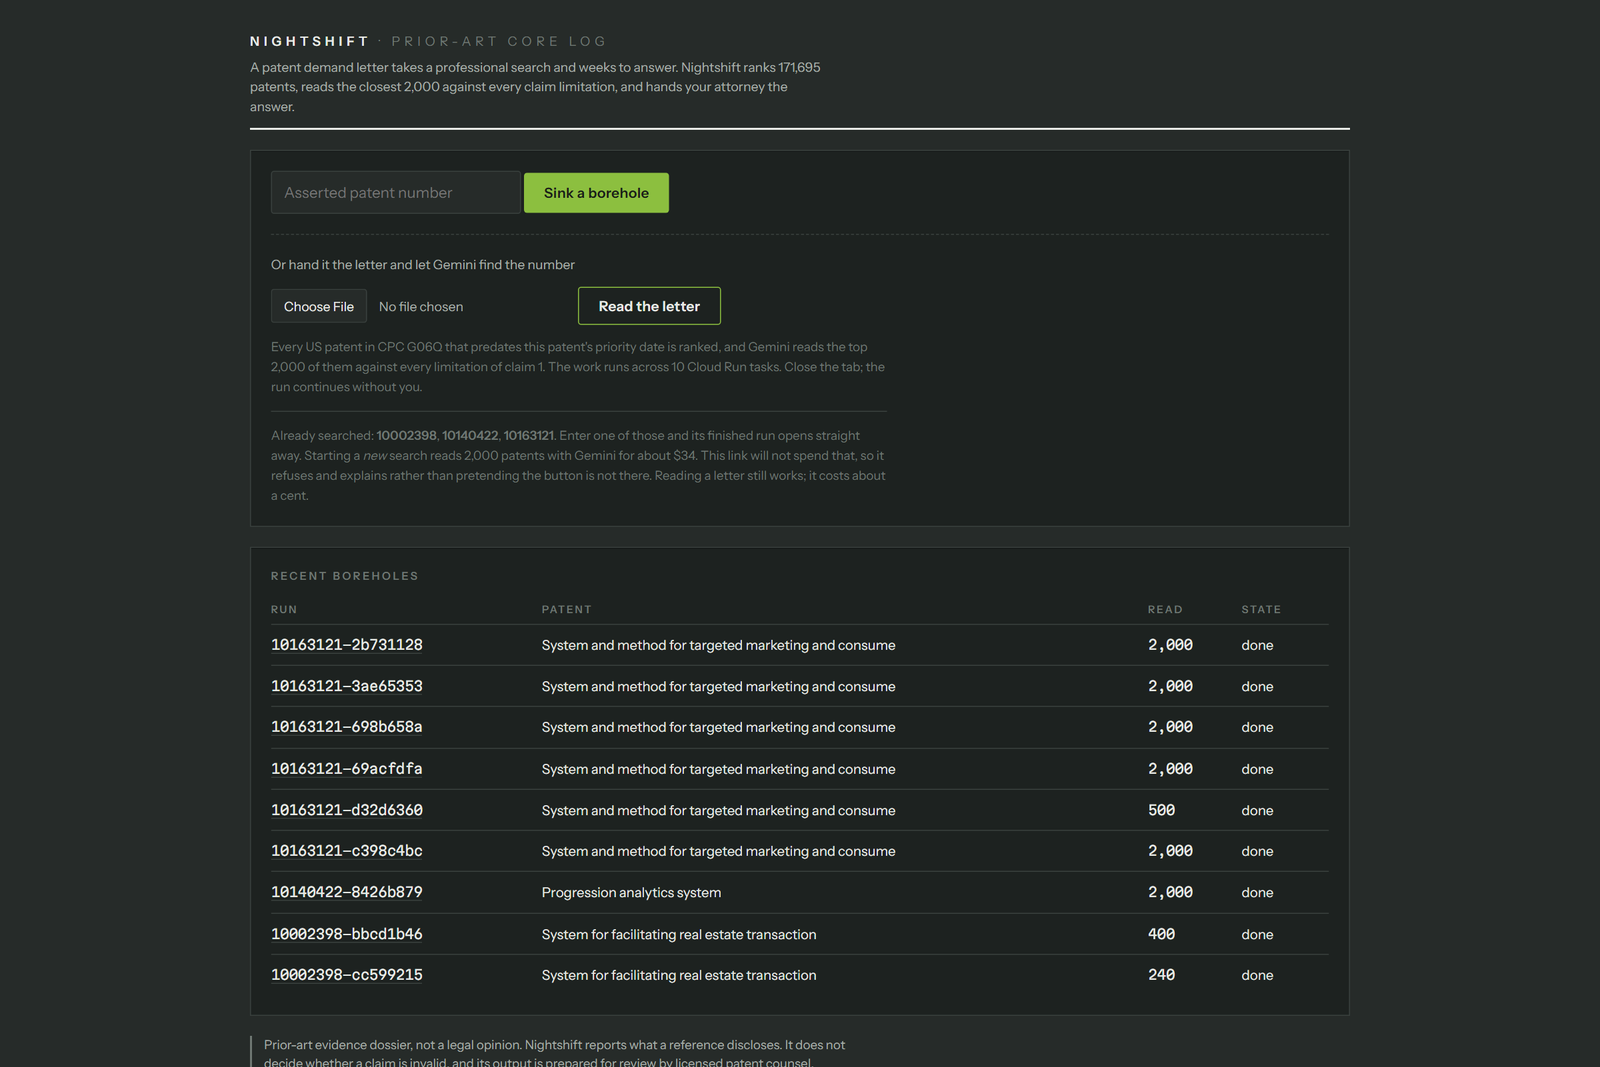
Every existing prior-art tool is a retrieval system: rank a corpus, show a human the top few dozen. That has a measurable ceiling: on the strongest embedding available, a top-50 shortlist still misses 59.7% of the references a USPTO examiner actually applied. Nightshift is a judgment system: a vector pass narrows 171,695 patents, then Gemini reads two thousand of them, not fifty, deciding for each whether it discloses each limitation. Blinded against real USPTO office-action citations: 97.5% recall of examiner-applied anticipation refs (n=40), 92.5% on obviousness (n=40), 18.8% on a control set never cited. On the demo run, 4 minutes across 10 Cloud Run tasks, $34.57, it independently surfaced the examiner's own X-cite at depth 218, plus a 1998 reference the examiner missed that teaches six of seven limitations outright.

AllThingsAgenticTheTaskmasterGoogle Cloud
Python Can't Weakref a ValueError. Sentry's Deduplication Found Out the Expensive Way: 1024 KB per Live Asyncio Task.
Aug. 2026
Winner
12 min read

Python Can't Weakref a ValueError. Sentry's Deduplication Found Out the Expensive Way: 1024 KB per Live Asyncio Task.

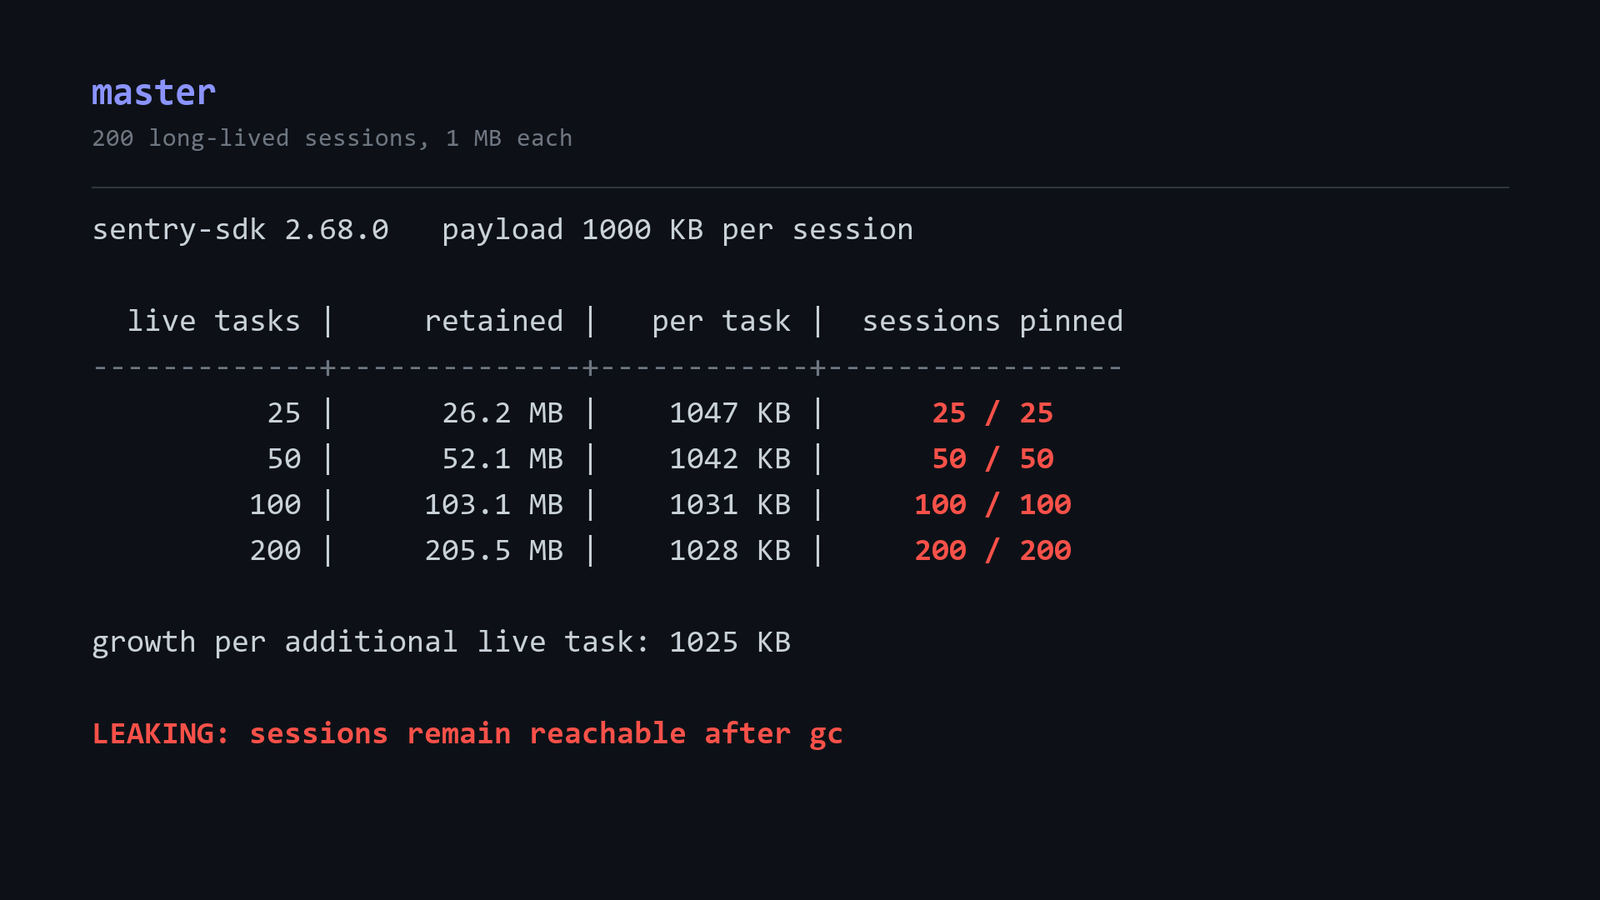
sentry-python's DedupeIntegration stops the same error being reported twice by remembering the last exception. Remembering an exception is exactly what you must not do: an exception holds its traceback, a traceback holds its frames, a frame holds every local. The SDK knew this and stored a weakref.ref(exc). The three lines under the comment `# we can only weakref non builtin types` do the one thing the weakref existed to prevent: an `except TypeError:` catches Python's refusal to weakref a builtin and quietly holds the exception itself. Under asyncio each task keeps its own copy in a ContextVar, so 200 long-lived sessions pin 205 MB, all reachable after gc.collect(). Two attempts before the fix, a value fingerprint that fails the SDK's own tests, an id-based fingerprint that collapses 2000 distinct errors into 2 keys, then the identity-token approach that keeps behaviour unchanged and takes retained down to 0.5 MB.

BugSmashClearTheLineupSentry
Still Here: Everyone Believes Black Dogs Get Left Behind. I Checked 99,916 Shelter Records. They Don't.
Aug. 2026
Winner
10 min read

Still Here: Everyone Believes Black Dogs Get Left Behind. I Checked 99,916 Shelter Records. They Don't.

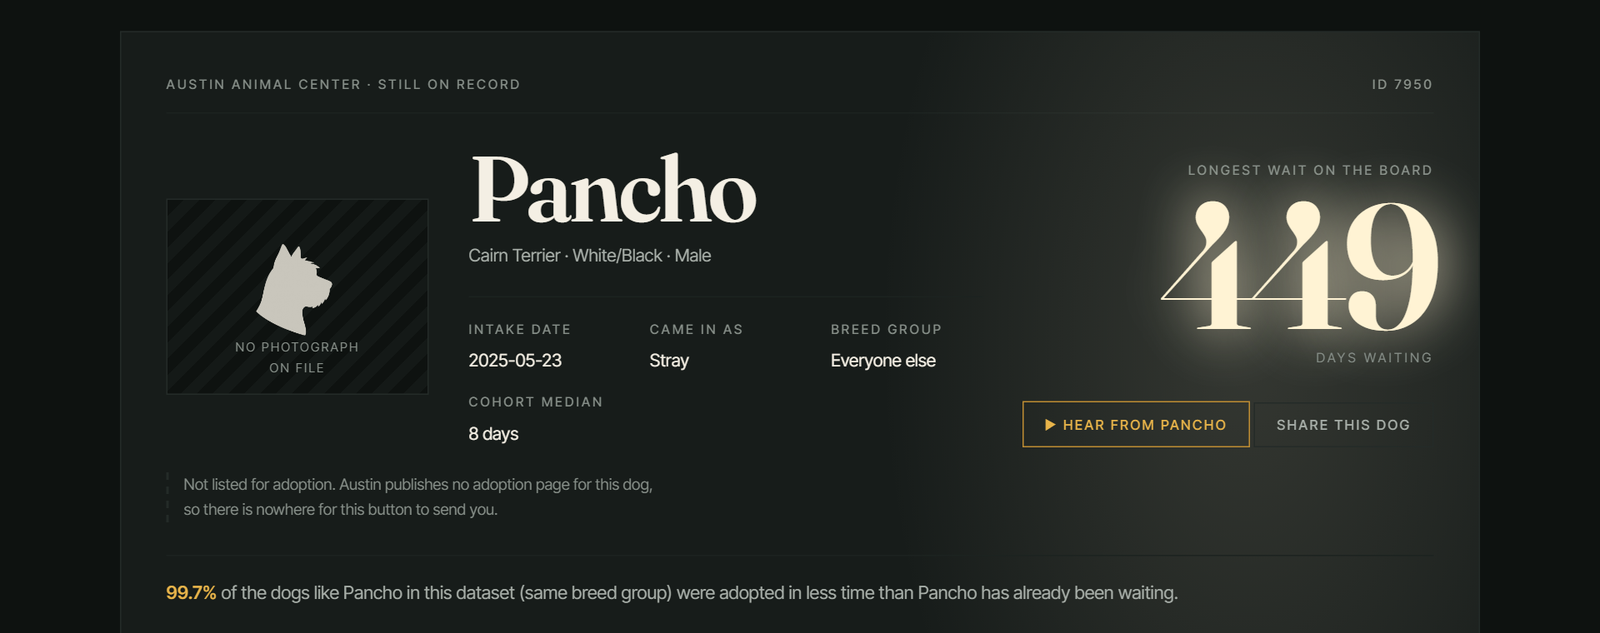
510 dogs have an intake record at the Austin animal shelter and no outcome record. Still Here is the board, ordered by how long they have waited. The one at the top is Pancho, 449 days. Then I went looking for the reason the dogs at the top are the ones at the top, and the answer surprised me: black dog syndrome does not appear in 99,916 completed stays, the colors that wait are the coats bully-type dogs come in. Hold breed constant and coat moves the median by at most 7.5 days; change the breed and it moves by 20.

WeekendChallengeDogDaysSnowflake
Assay: A Skincare Tracker with an Error Bar. Cropping the Same Photo Moves Texture by 5.81 Points, So a Verdict Only Fires When the Change Beats That Floor on Your Face.
Aug. 2026
11 min read

Assay: A Skincare Tracker with an Error Bar. Cropping the Same Photo Moves Texture by 5.81 Points, So a Verdict Only Fires When the Change Beats That Floor on Your Face.

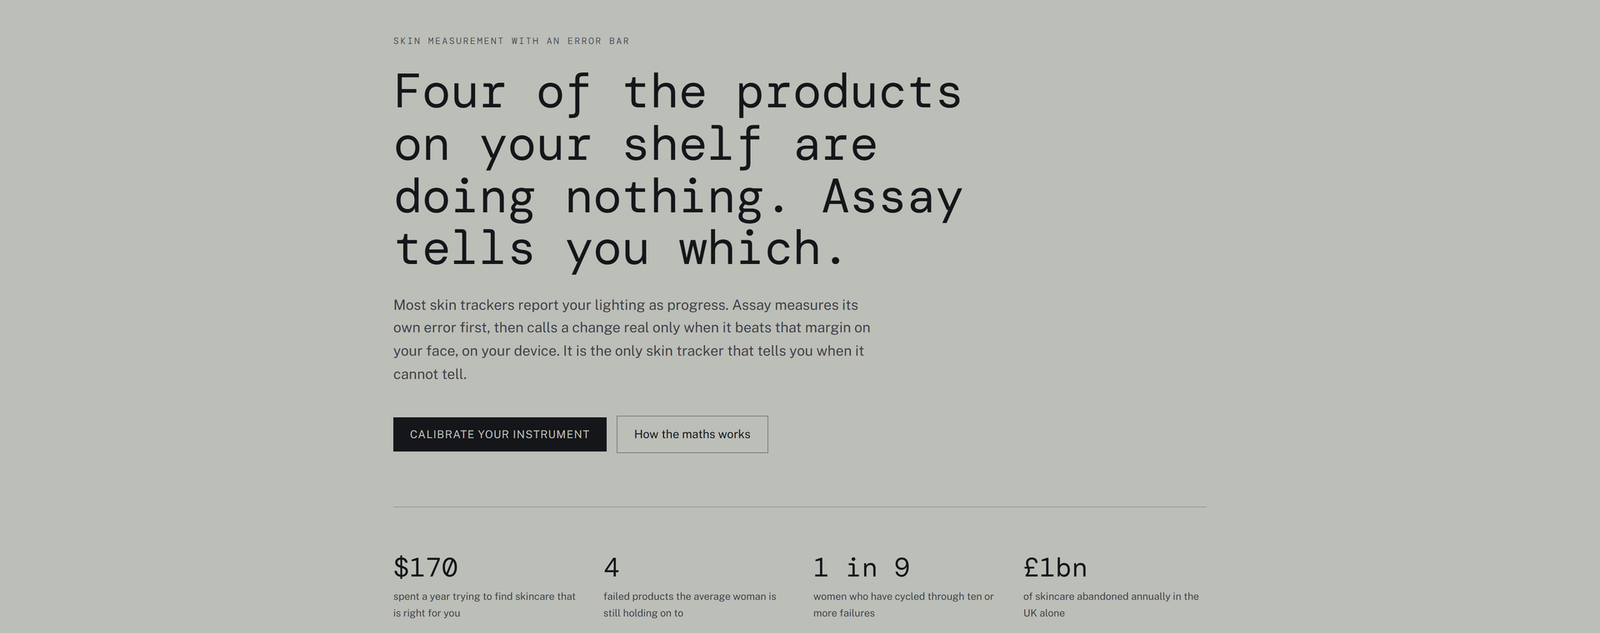
The measurement exists: YouCam's Skin Analysis API scores sixteen skin outputs from a photograph, and it is a genuinely good instrument (byte-identical input gives byte-identical output). The problem is that a score reported without its error is a number you cannot make a decision with. On my own face with one variable changed at a time, brightness ±8% moves blemishes by 4.85 points and cropping the same photograph differently moves texture by 5.81. A realistic four-week treatment effect is about five. Assay measures its own error first, then calls a change real only when it beats that floor.

YouCamHackathonYouCam Skin Analysis APIPerfect Corp
Unsay: An AI Medication-Safety Agent that Goes Back and Un-Says What It Told You. When the FDA Escalates a Recall, It Corrects Every Named Patient It Already Reassured, in Seconds.
Aug. 2026
Winner
13 min read

Unsay: An AI Medication-Safety Agent that Goes Back and Un-Says What It Told You. When the FDA Escalates a Recall, It Corrects Every Named Patient It Already Reassured, in Seconds.

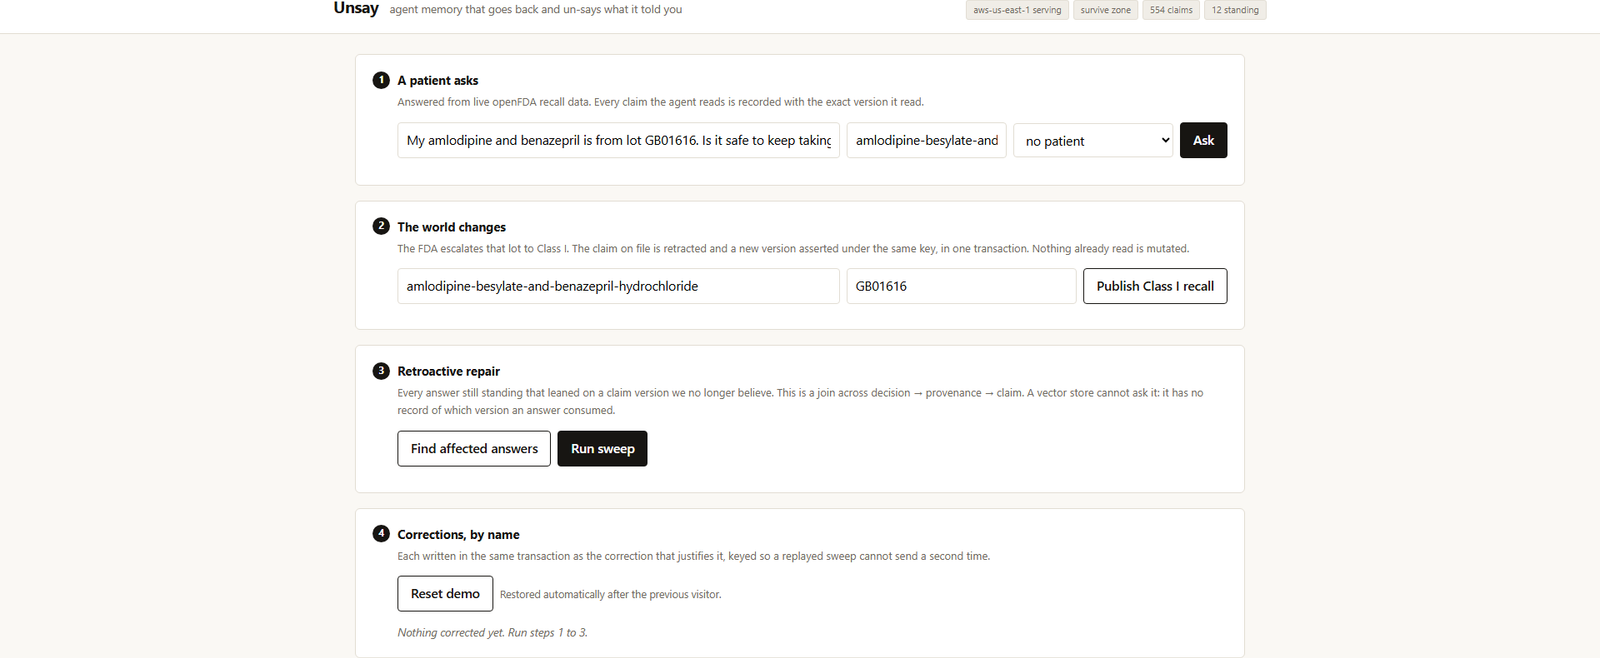
Agent memory has a failure mode retrieval quality cannot fix: stale context. Similarity to a stored memory does not prove the memory is still true. For most agents that is embarrassing. In a pharmacy it is a Class I recall. Unsay's fix is a bitemporal schema on CockroachDB (`valid_from`/`valid_to` for the world, `asserted_at`/`retracted_at` for this system's belief), and a join no vector store can express: every answer still standing that leaned on a claim version we no longer believe. The replay still works past the AS OF SYSTEM TIME horizon, and every correction is exactly-once across a region failure.

CockroachDBHackathonCockroachDBBitemporal
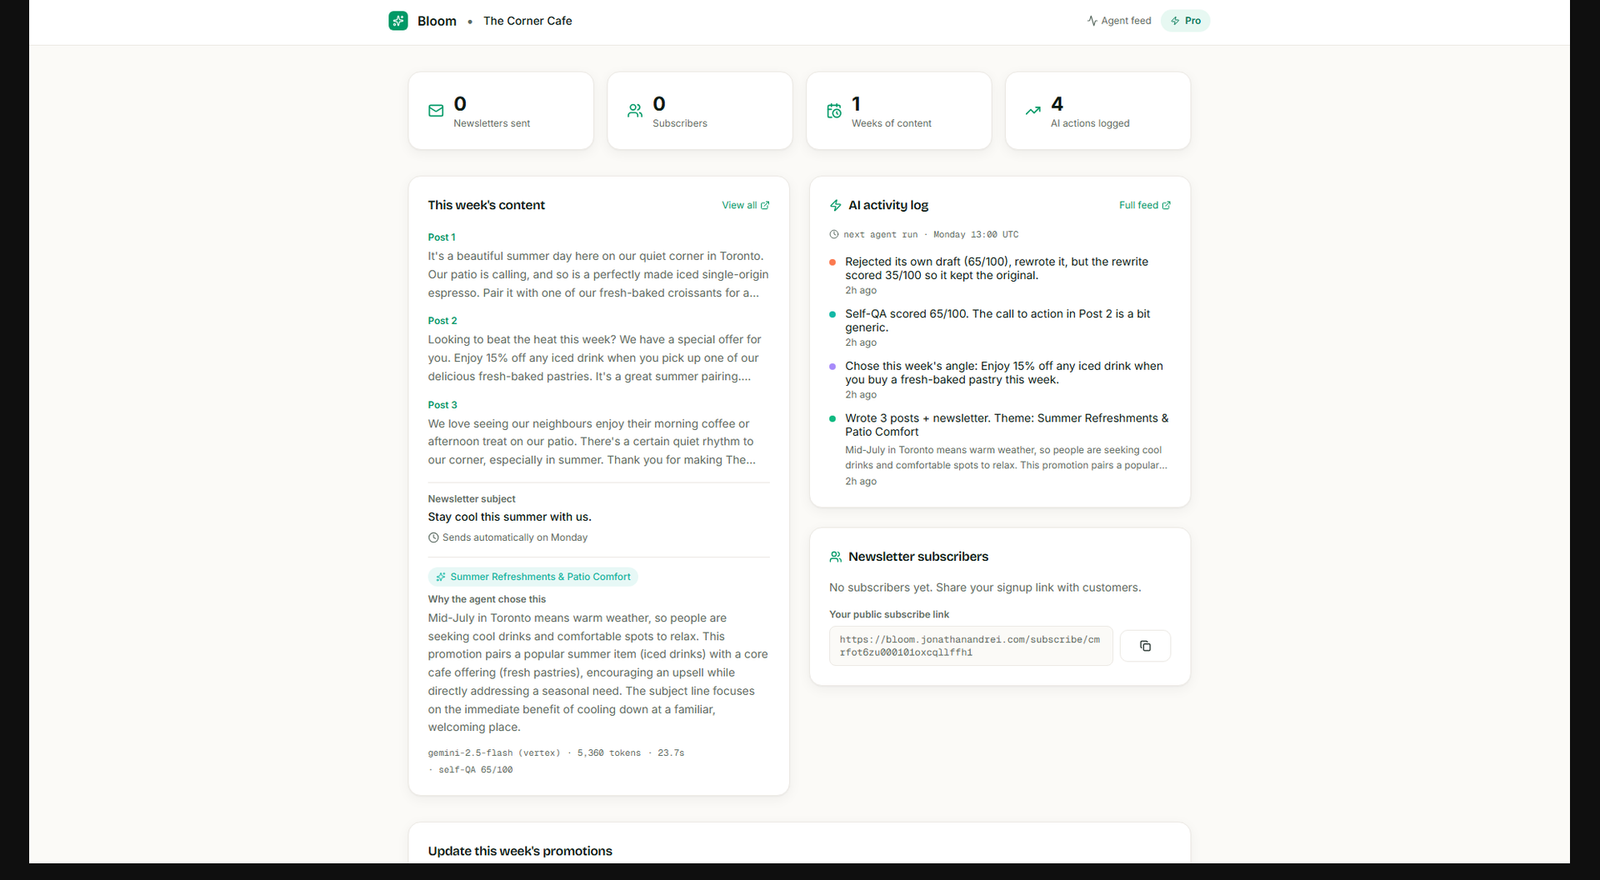
Bloom: Nobody Cancels, They Just Stop Coming. Bloom Reads Each Client's Own Visit Rhythm, Flags the Ones Drifting from It, and Writes a Personal Note to Each. Rules Decide Who, Gemini Decides What to Say.
Jul.-Aug. 2026
12 min read

Bloom: Nobody Cancels, They Just Stop Coming. Bloom Reads Each Client's Own Visit Rhythm, Flags the Ones Drifting from It, and Writes a Personal Note to Each. Rules Decide Who, Gemini Decides What to Say.

A typical salon loses about 40% of its clients every year, a first-timer who does not rebook within 30 days has about a one-in-five chance of ever returning, and a loyal regular is worth several hundred dollars a year. The signal is invisible because it is an absence, spread across hundreds of people who each have their own rhythm. Bloom's architecture is the idea: rules decide WHO (deterministic risk engine on each client's own median visit gap), Gemini decides WHAT TO SAY (a short note in the owner's voice, referencing that person's real history). The demo of the whole thesis is two clients: Aisha and Jane are both 44 days since their last visit; Aisha comes every 8 weeks, Jane comes every 4. Any tool that flags 'no visit in 60 days' is wrong about one of them.

GeminiXPRIZEHackerFundGoogle Gemini 2.5 Flash
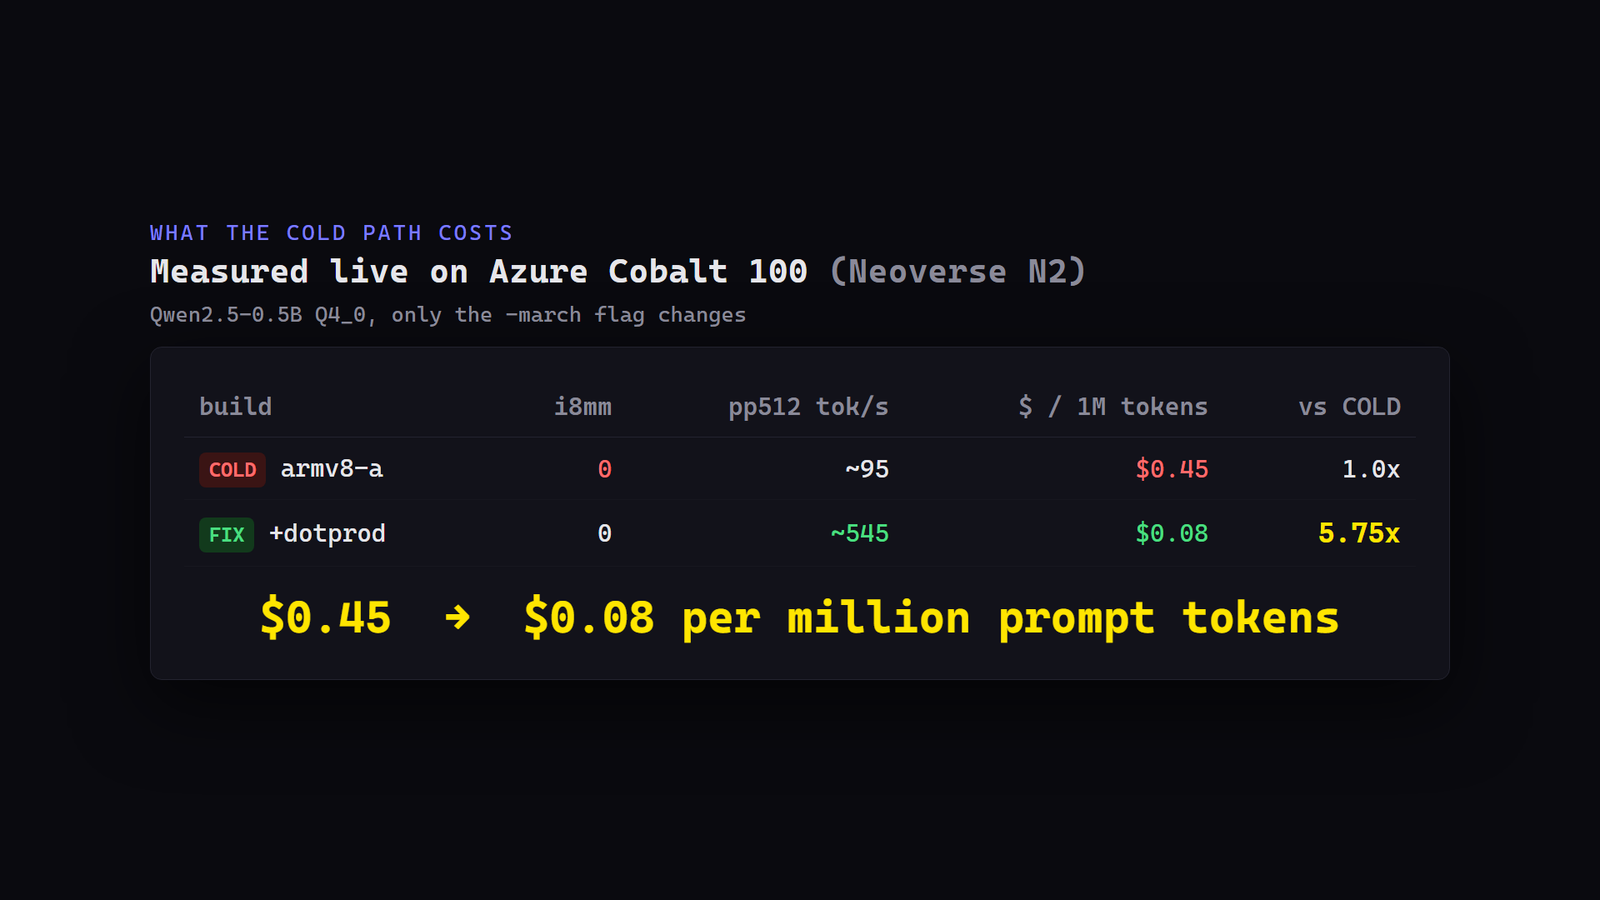
coldpath: The Ollama Windows-on-Arm Build Ships with the Matrix Unit Off. One-Line Fix Filed Upstream, 5.75x on Prompt Processing.
Aug. 2026
12 min read

coldpath: The Ollama Windows-on-Arm Build Ships with the Matrix Unit Off. One-Line Fix Filed Upstream, 5.75x on Prompt Processing.

I could not answer a basic question about my own Arm machine: when a local LLM runs, is it actually using the chip's matrix hardware, or silently falling back to scalar code? So I wrote the tool that answers it, pointed it at the ecosystem, and found the most popular Windows-on-Arm LLM runner cold. coldpath is a Capstone-based AArch64 disassembler that proves a binary contains SME, i8mm, and dotprod instructions; the finding is Ollama's official win-arm64 build has zero of any of them. One-line fix filed upstream (PR #17654), 5.75x recovered on prompt processing measured live on Azure Cobalt 100, gated in CI as a reusable GitHub Action.

ArmCloudAIAArch64Neoverse N2
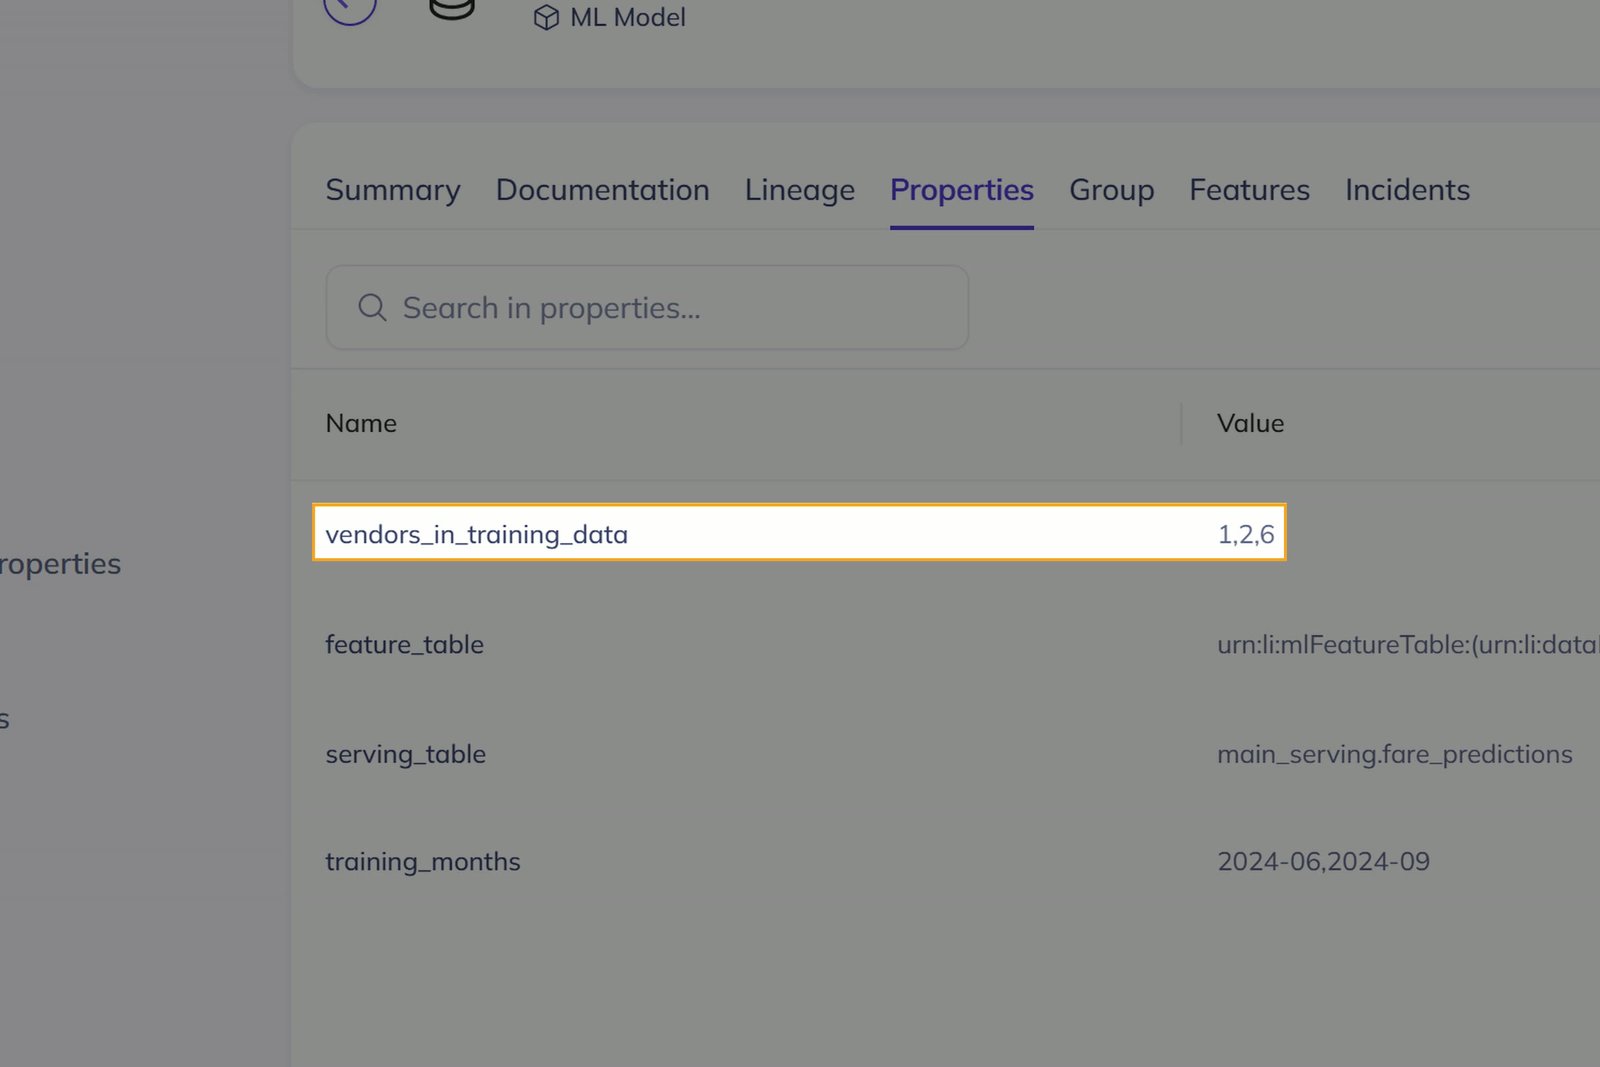
Culprit: A Stack Trace for Model Decay. $90,322 of Model Error Traced to One Column That Went from Max 6 to Max 7.
Aug. 2026
Winner
13 min read

Culprit: A Stack Trace for Model Decay. $90,322 of Model Error Traced to One Column That Went from Max 6 to Max 7.

Freshness, volume, null-rate, and schema checks were all green. The model had been quietly wrong for six months. Culprit walked DataHub's ML lineage back to the column that did it, filed the incident into the graph with the dollars attached, wrote the fix, executed dbt build against the real warehouse to verify it, rejected its own first patch that would have deleted 87,693 rows, and only then opened the PR. $90,322 of attributable model error priced against a counterfactual control on 19.3M real NYC taxi records.
BuildWithDataHubHackathonDataHubMCP
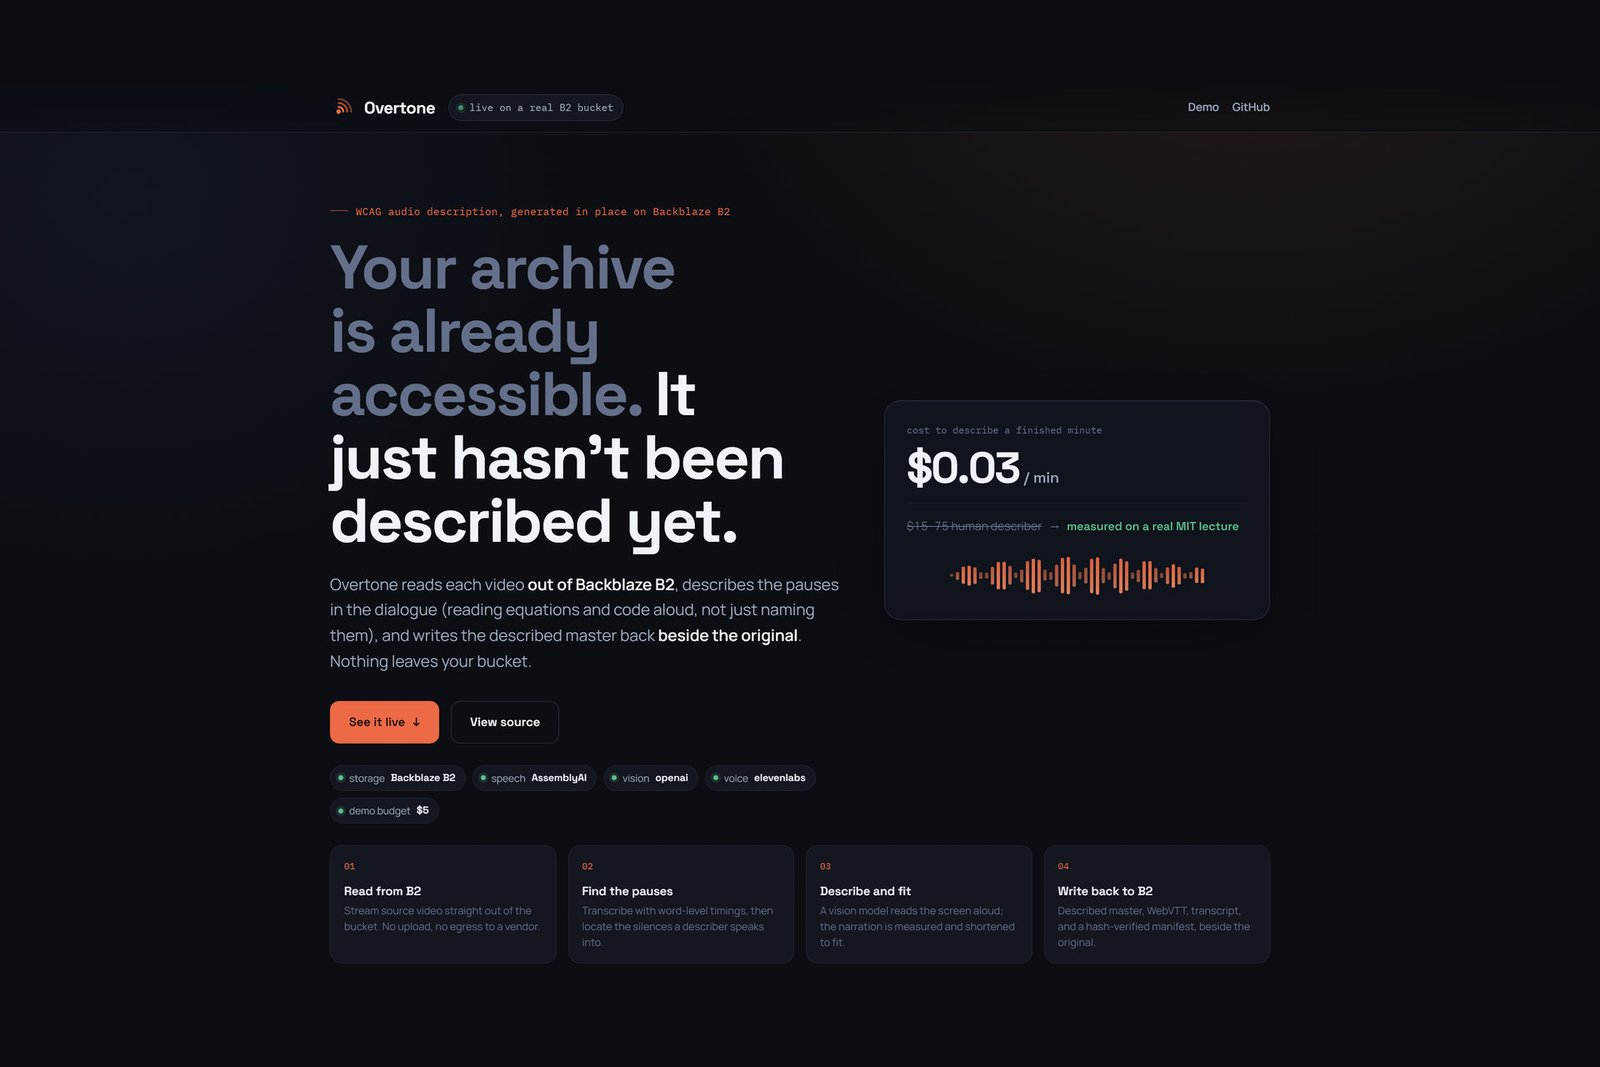
Overtone: WCAG Audio Description for a Whole Video Archive at ~$0.03 a Minute, Generated in Place on Backblaze B2
Jul. 2026
11 min read

Overtone: WCAG Audio Description for a Whole Video Archive at ~$0.03 a Minute, Generated in Place on Backblaze B2

WCAG requires a spoken audio-description track on prerecorded video: a narrator describing what is on screen in the pauses in the dialogue. Public universities owe this under federal law by April 26, 2027, but human describers charge $15-$75 per finished minute, so archives go undescribed or get deleted. Overtone reads each video out of a Backblaze B2 bucket, generates the description in place, and writes the described master back beside the original. Measured on a real 3-minute MIT OpenCourseWare lecture: about nine cents to describe, roughly three cents a minute end to end. Every generative step runs through Genblaze, with automatic provider failover so an archive-scale run does not die on a single transient error.

BackblazeGenblazeHackathonBackblaze B2Genblaze
Viva: 91 Full-Mark C Submissions Out of 626 Hide a Defect the Autograder Never Checked
Jul. 2026
10 min read

Viva: 91 Full-Mark C Submissions Out of 626 Hide a Defect the Autograder Never Checked

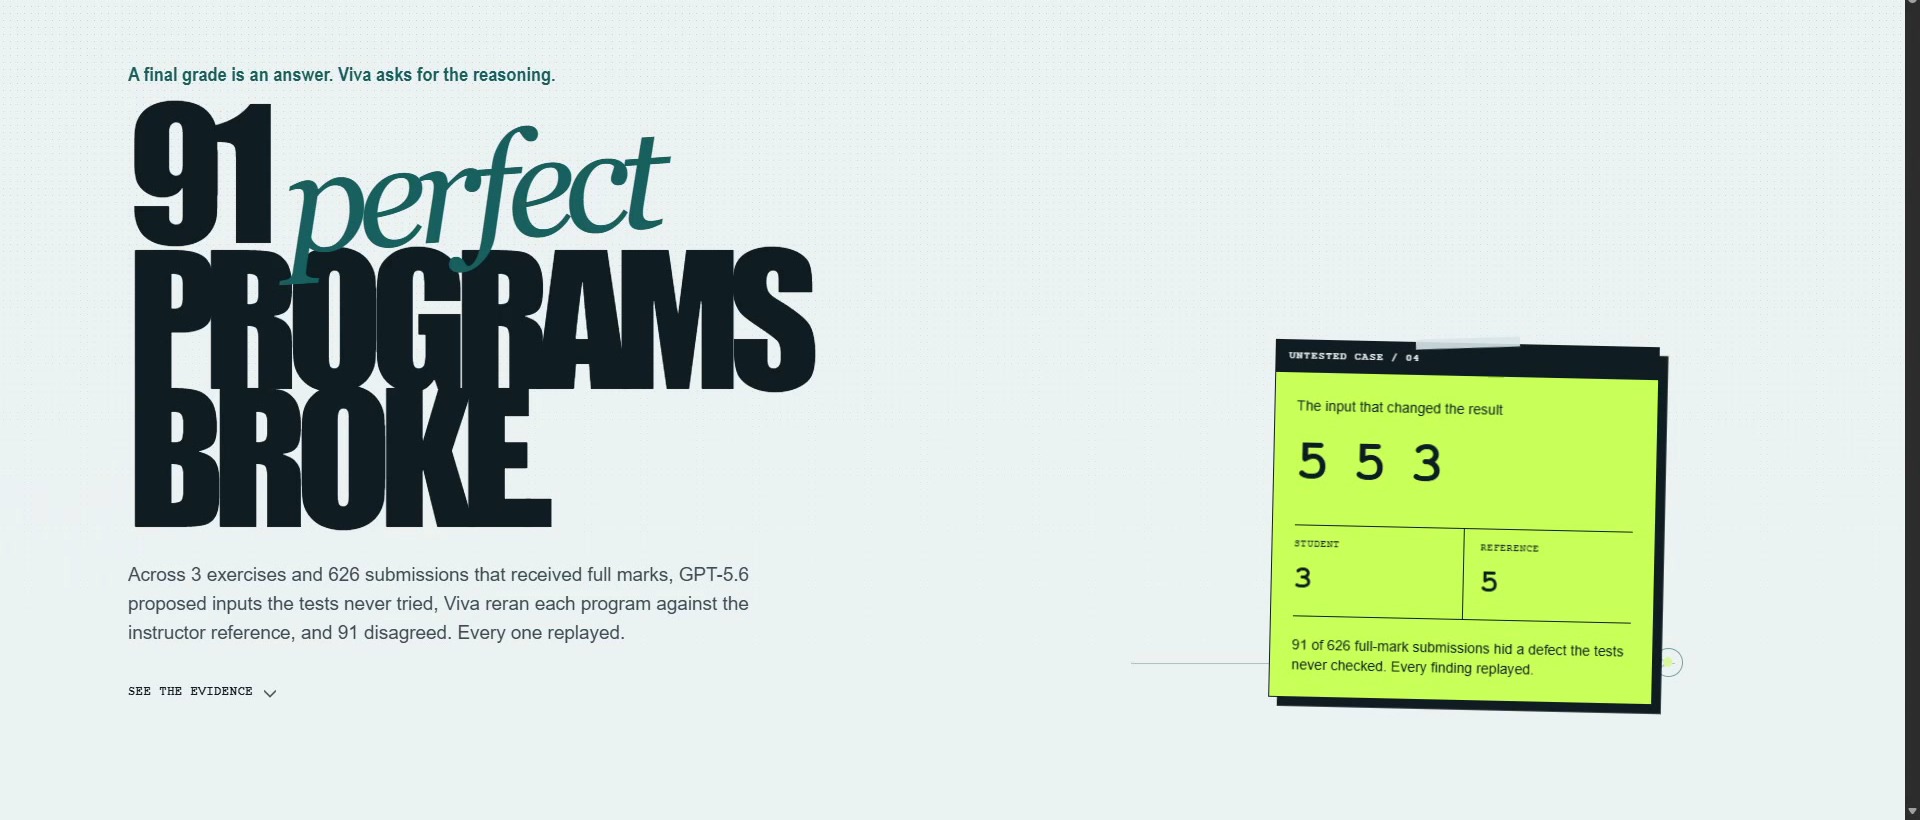
A passing test suite proves a program worked on the inputs the instructor happened to check. It does not prove the student can explain what the program does. Viva closes that gap: GPT-5.6 reads the assignment and proposes an input the test suite never tried, Viva runs the student program and the reference on it, and it only asks the student a question when the two programs disagree. On 626 real C submissions that earned full marks, 91 (14.5%) hide a defect the autograder never checked, and 83 of those (13.3%) fail on an input as simple as `5 5 3`. Not a prediction, a replay: every finding carries a re-runnable command.

OpenAIBuildWeekGPT-5.6OpenAI Codex
LedgerPilot: Same Qwen, Same Ledger, Gate Off Posts 5 Wrong Entries and Gate On Posts 0
Jul. 2026
12 min read

LedgerPilot: Same Qwen, Same Ledger, Gate Off Posts 5 Wrong Entries and Gate On Posts 0

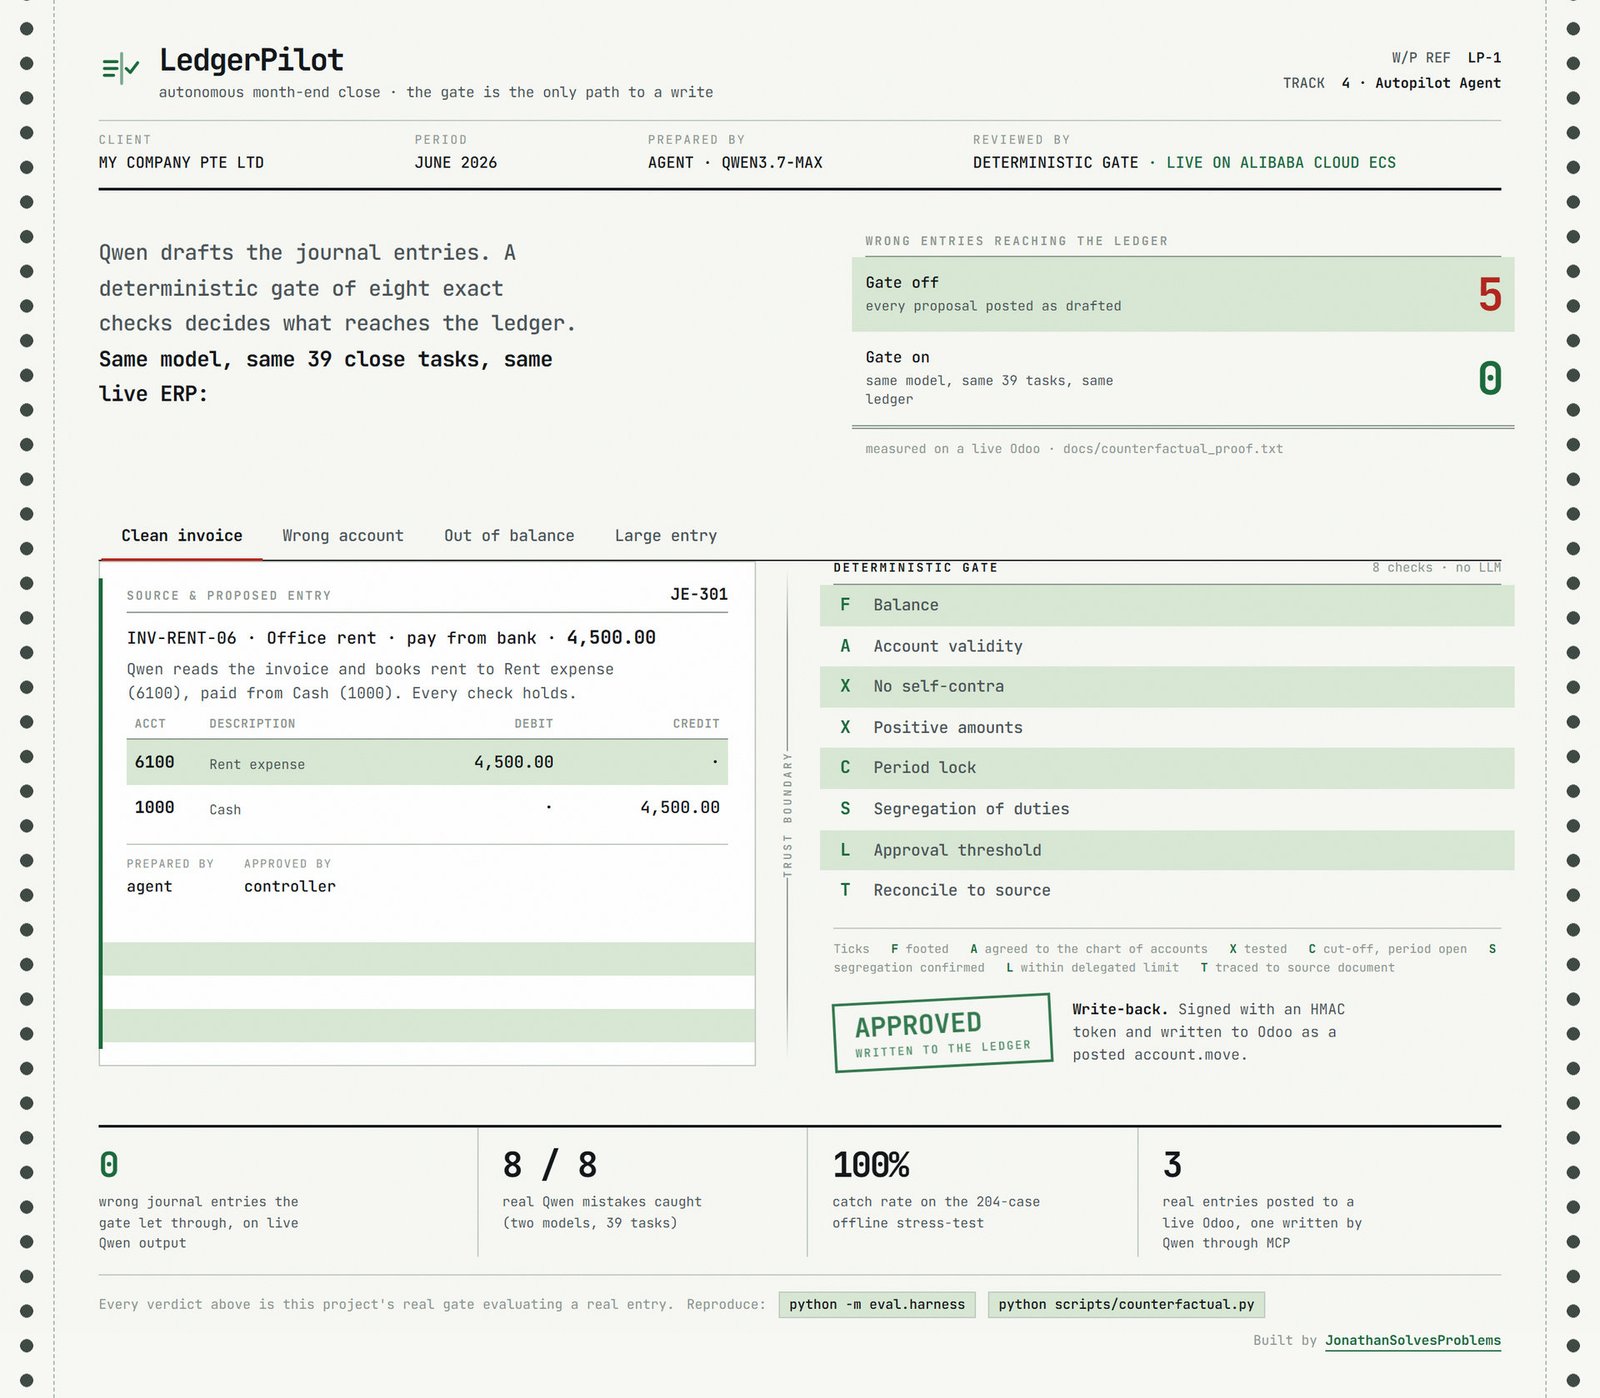
Month-end close is the wrong workflow to give a hallucinating AI a keyboard on. LedgerPilot is a month-end-close agent where Qwen proposes journal entries and a deterministic gate is the only path to a write. The counterfactual is the whole claim: same qwen-flash planner, same 39 close tasks, same live Odoo ledger, gate off posts 5 wrong entries (salaries paid out of Accounts Receivable, cost-of-goods to receivables and revenue, each one balanced, each one plausible), gate on posts 0. The model did not get better; the ledger did. Runs on Alibaba Cloud ECS, drives the write through MCP.

QwenCloudHackathonQwenAlibaba Cloud
Clatterfall: One Marble, One Subreddit, One Shared Run a Day, One Machine Nobody Can Build Alone
Jul. 2026
11 min read

Clatterfall: One Marble, One Subreddit, One Shared Run a Day, One Machine Nobody Can Build Alone

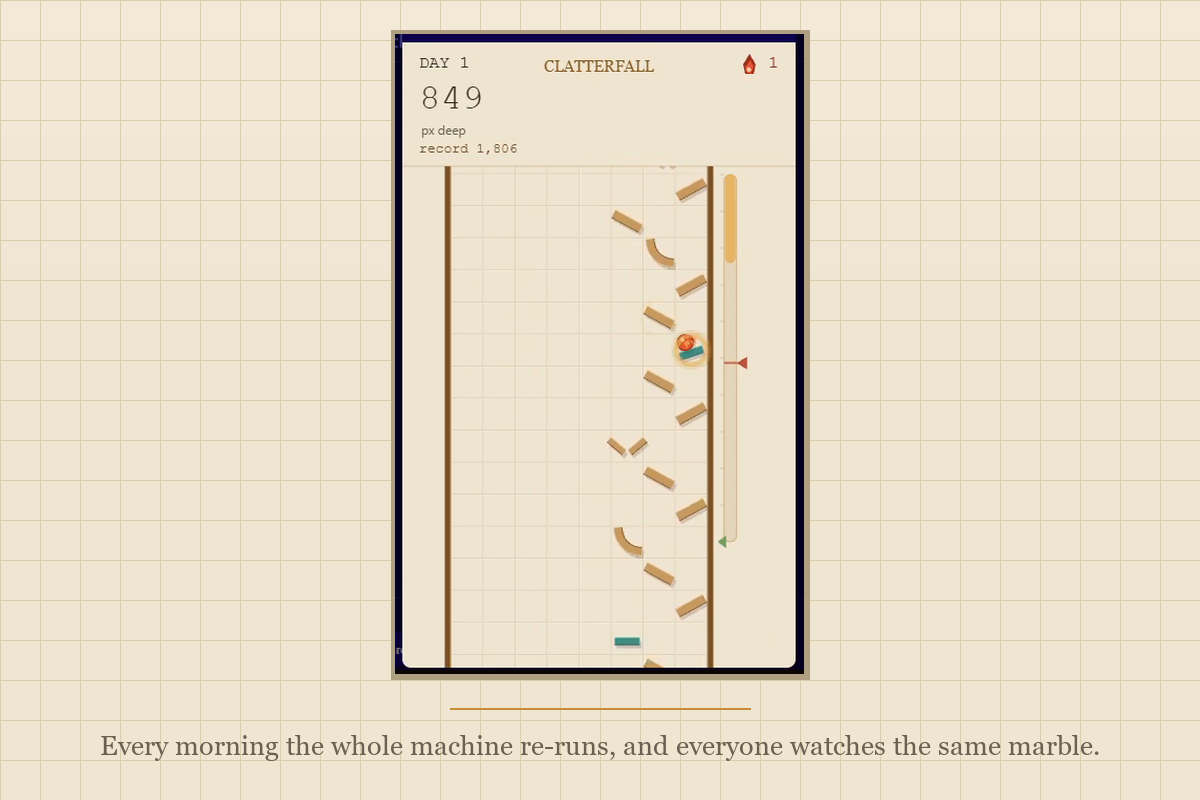
r/Clatterfall is one continuous descent, built by a crowd, one part per person per day. Every morning the entire committed machine re-runs as a single canonical simulation that everyone watches together, and the parts the marble abandons dissolve. Three rules do the load-bearing work: you can only build on the marble's actual path (the frontier), the daily run is server-simulated once and replayed pixel-identical everywhere, and parts the marble stops touching dissolve. Non-AI and proud: every pixel drawn from Phaser Graphics primitives at runtime.

RedditGamesHackathonReddit DevvitPhaser
Loose Ends: The Slack Agent That Refuses to Close a Loop Until It Sees Evidence
Jul. 2026
12 min read

Loose Ends: The Slack Agent That Refuses to Close a Loop Until It Sees Evidence

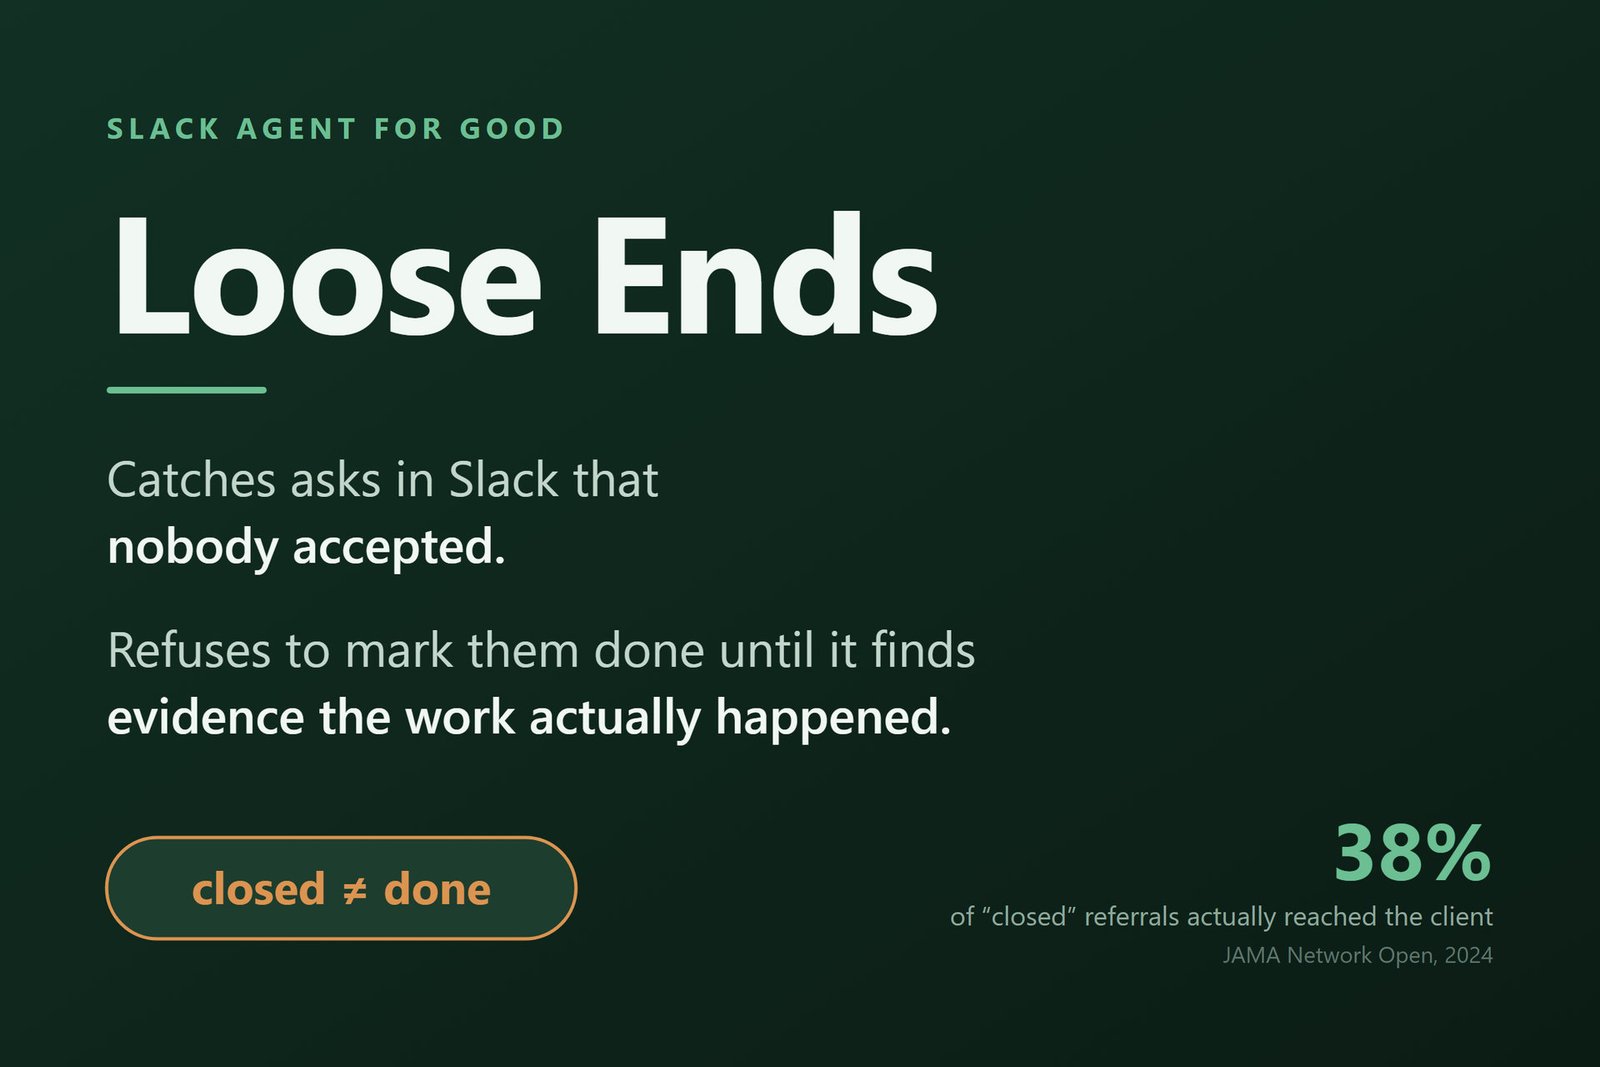
In a nonprofit or mutual-aid Slack, a dropped 'can someone follow up with the Diaz family?' is not a slipped deck, it is a person not served. Every commitment bot on the market marks a loop done when a timer fires or when someone clicks 'done'. Loose Ends watches the same channel for a later message that proves the work actually happened, and treats a deadline passing without proof as BROKEN. Grounded in a real number: 93% of social-services cases were marked closed, only 38% actually delivered the service (JAMA Network Open, 2024). Closed is not done.

SlackAgentHackSlack BoltSlack Real-Time Search
Pick Your Side: I Built a Machine That Manufactures a World Cup Team, Grounded in Real History
Jul. 2026
Winner
8 min read

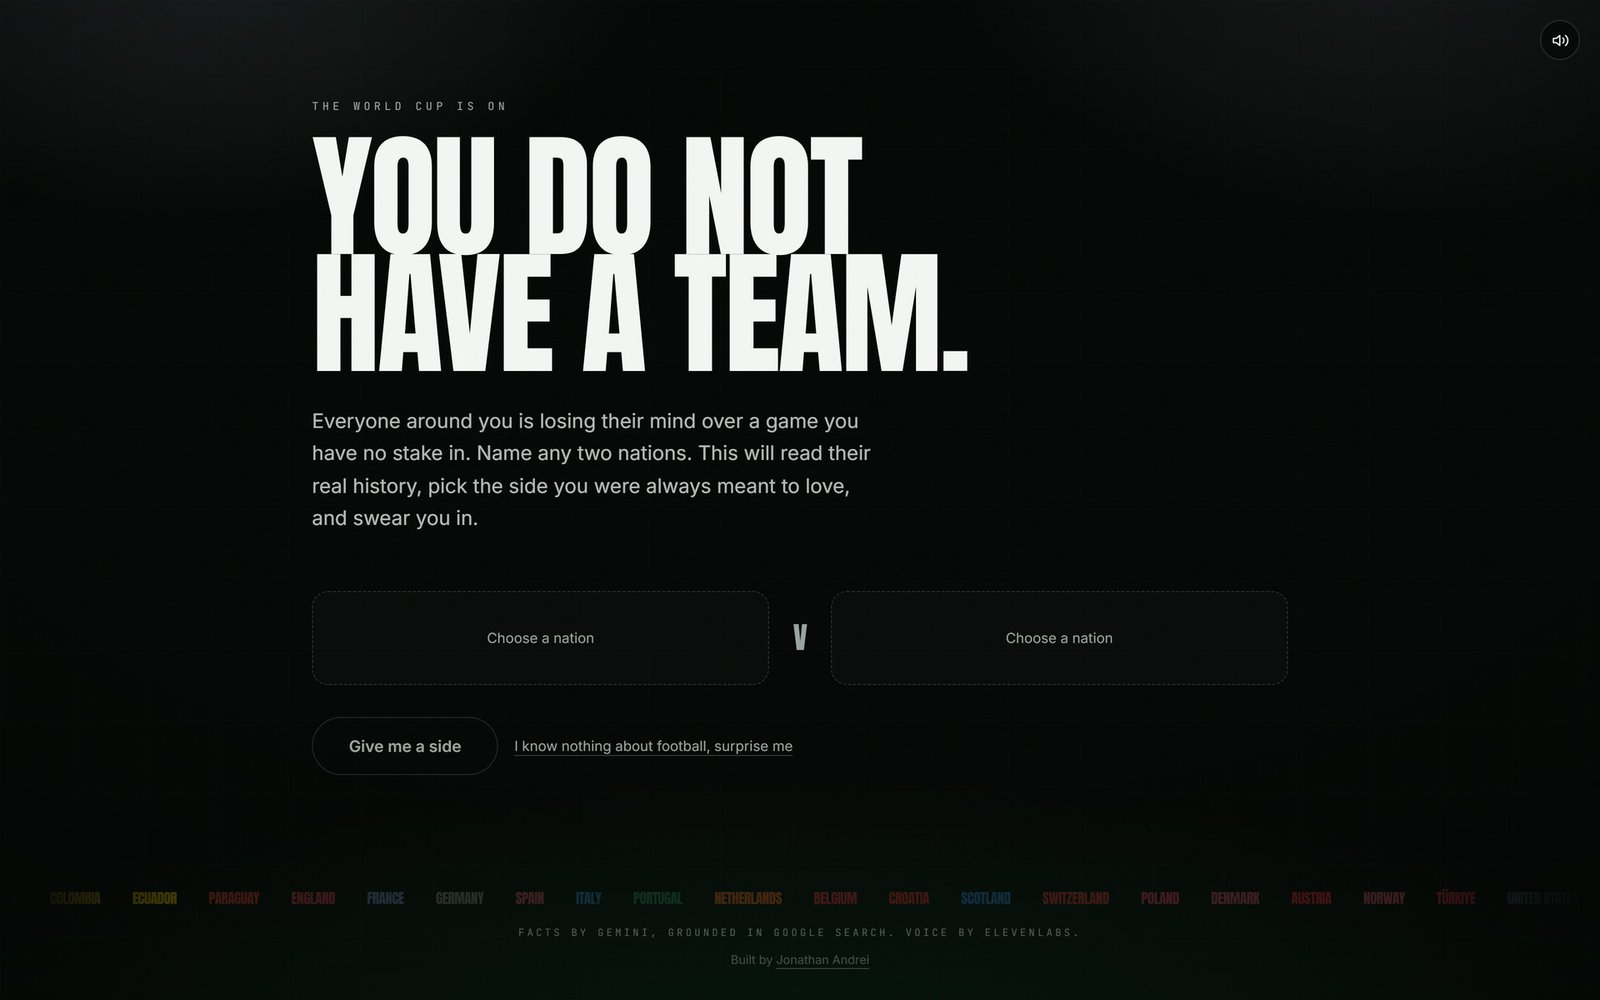
Pick Your Side: I Built a Machine That Manufactures a World Cup Team, Grounded in Real History

Every World Cup app is built for the people who already care. This one is for everybody else: name any two nations and it reads their real history, picks the side you were always meant to love, and a stadium announcer swears you in. The whole architecture bends around one rule: none of the history is invented. Gemini researches with Google Search grounding on, then rewrites into a strict responseSchema, then ElevenLabs performs it over a stadium crowd that ElevenLabs also generated.

weekendchallengedevchallengegoogleai
FlakeWarden: 90.7% Accuracy and a 0% Safety False-Positive Rate on Flaky-Test Triage, on UiPath Maestro
Jun. 2026
Winner
11 min read

FlakeWarden: 90.7% Accuracy and a 0% Safety False-Positive Rate on Flaky-Test Triage, on UiPath Maestro

Flaky tests are the most corrosive failure mode in CI: a red build might be a real regression or just noise, and engineers eventually start ignoring red builds until a real bug ships. FlakeWarden answers the only question that matters (real defect, flaky, or environment) with a deterministic flake-scorer for the clear cases and a grounded UiPath Agent Builder classifier for the ambiguous ones, orchestrated through Maestro with a human approving every change. 90.7% accuracy on a 150-case corpus, with 0% safety false-positive rate enforced by mechanism.

AgentHackUiPathUiPath Maestro
LotZero: Zero Oversells and Zero Double-Spends on a Global Live Auction, Proven on Aurora DSQL
Jun. 2026
10 min read

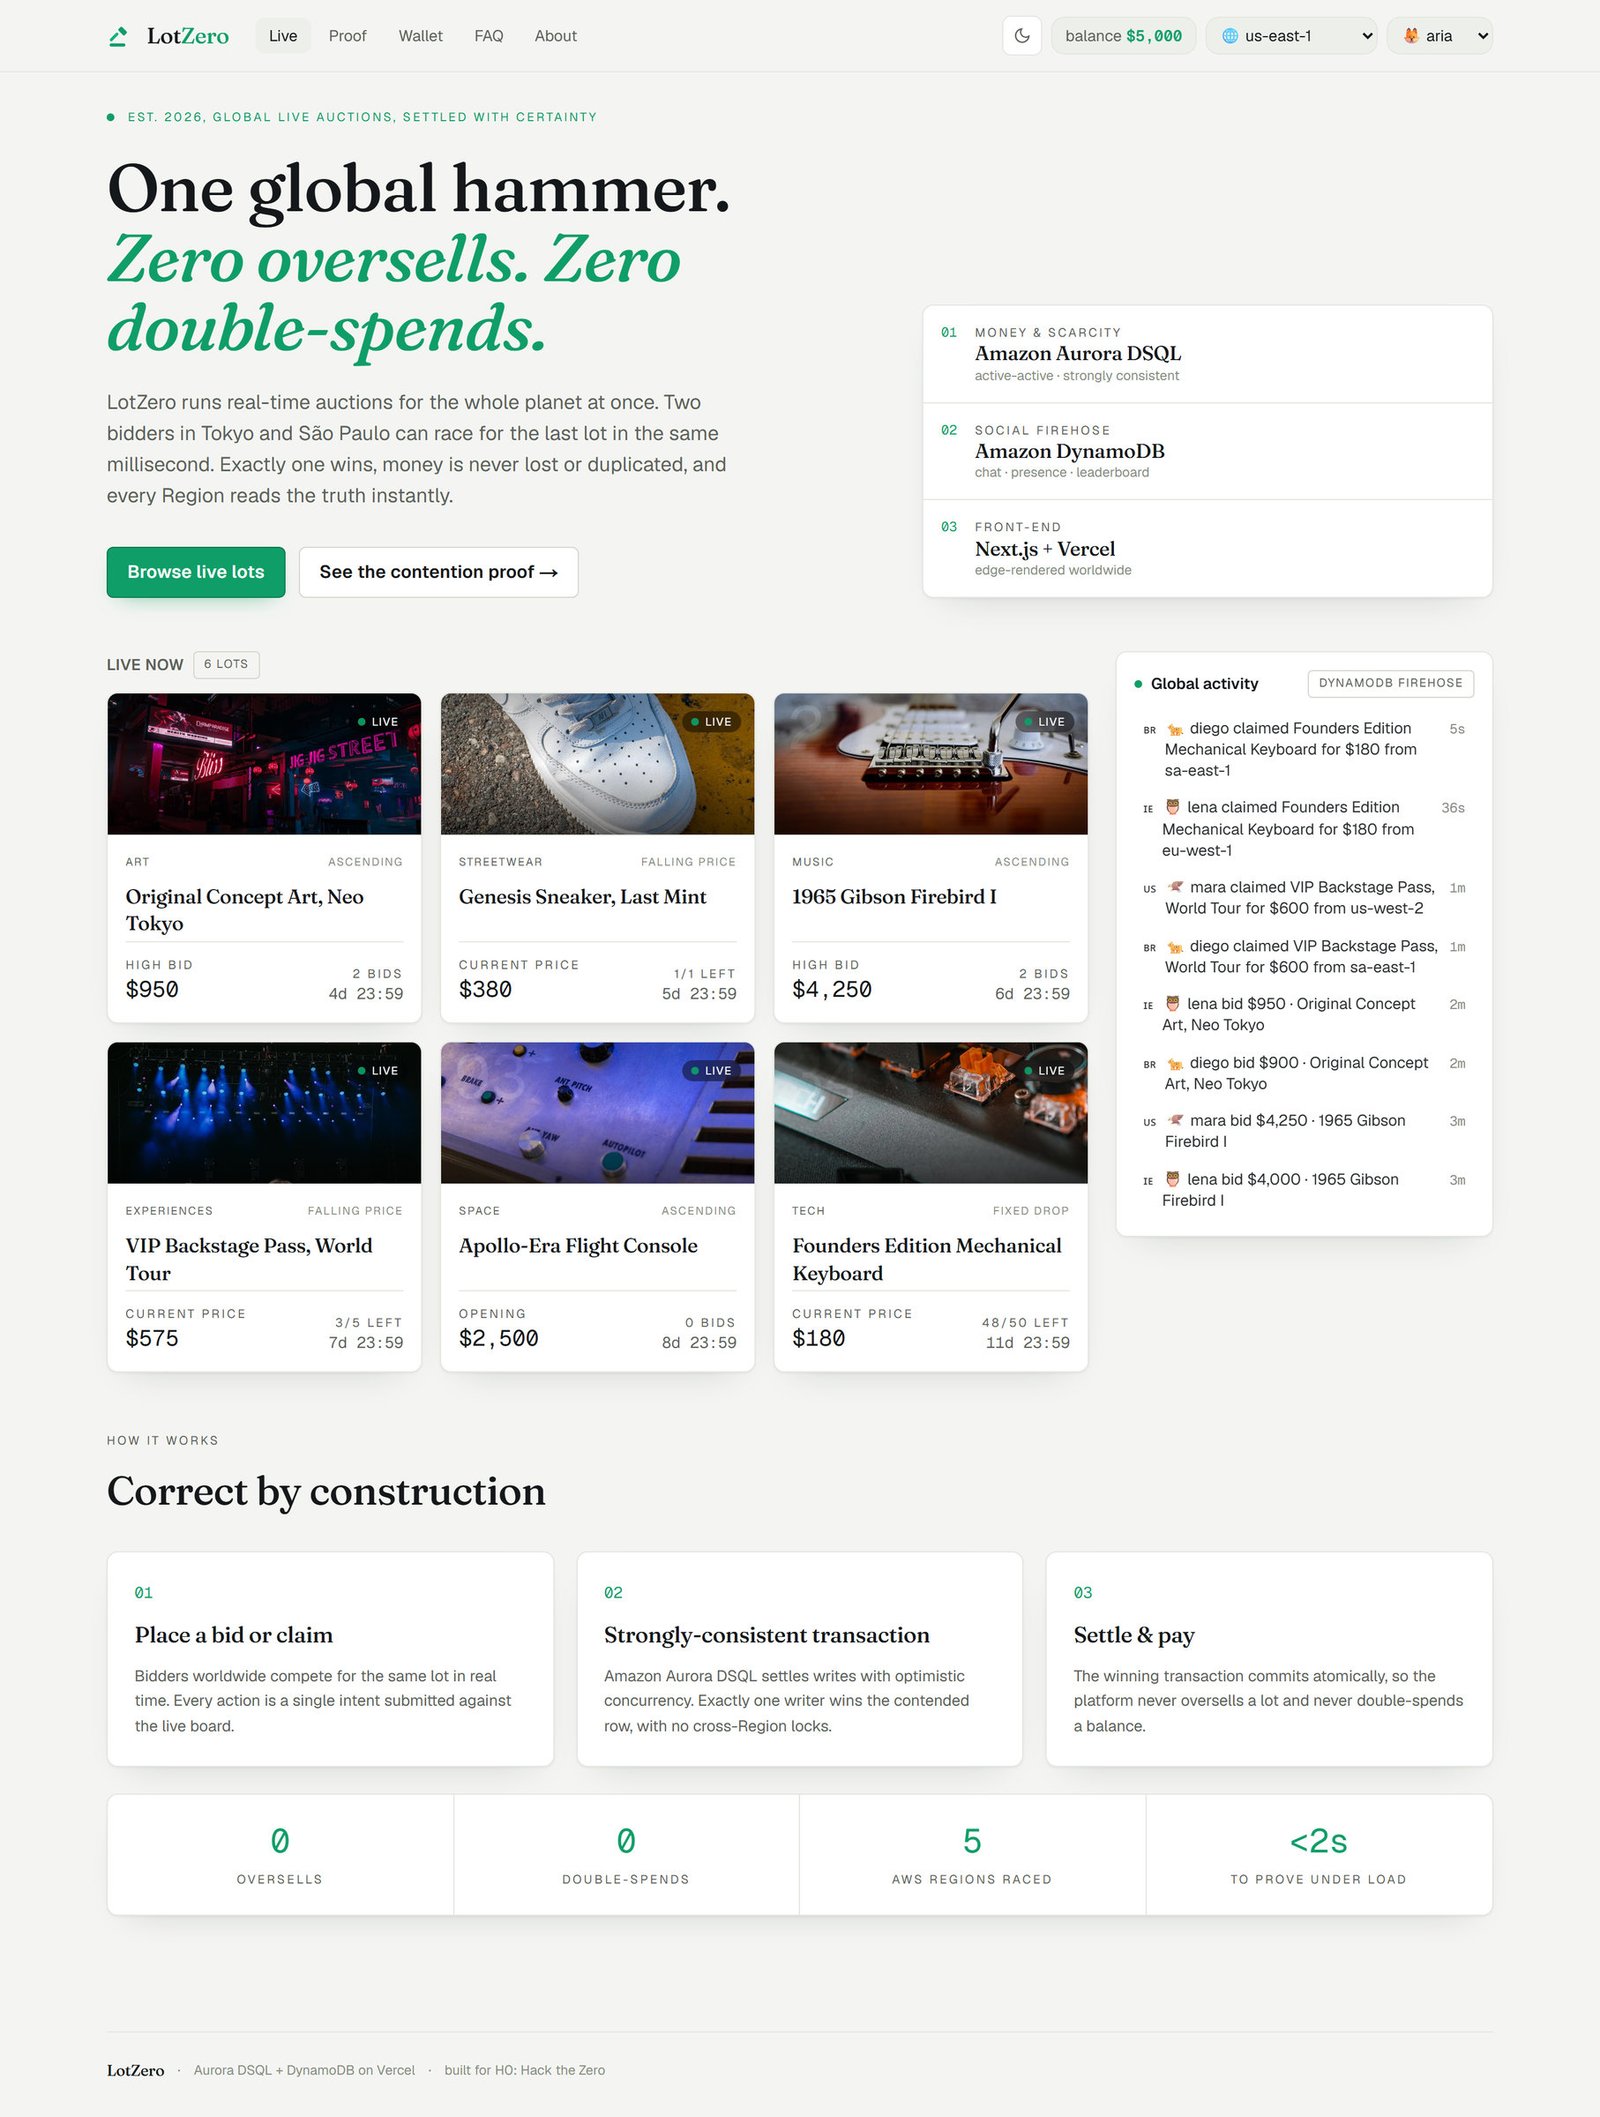
LotZero: Zero Oversells and Zero Double-Spends on a Global Live Auction, Proven on Aurora DSQL

Real-time global commerce used to force a choice: a single-Region SQL box (correct but slow for distant bidders) or a multi-Region eventually-consistent store (fast but unsafe for money). Aurora DSQL collapses that tradeoff. LotZero puts the money ledger on DSQL and the social firehose on DynamoDB, then proves the invariant with a contention console that fires hundreds of concurrent global claims and measures: zero oversells, zero double-spends.

H0HackathonAmazon Aurora DSQLAmazon DynamoDB
OrbitOnboard: I Used All Four GitLab Orbit Query Types to Generate a Contributor Starter Kit in 10 Seconds
Jun. 2026
11 min read

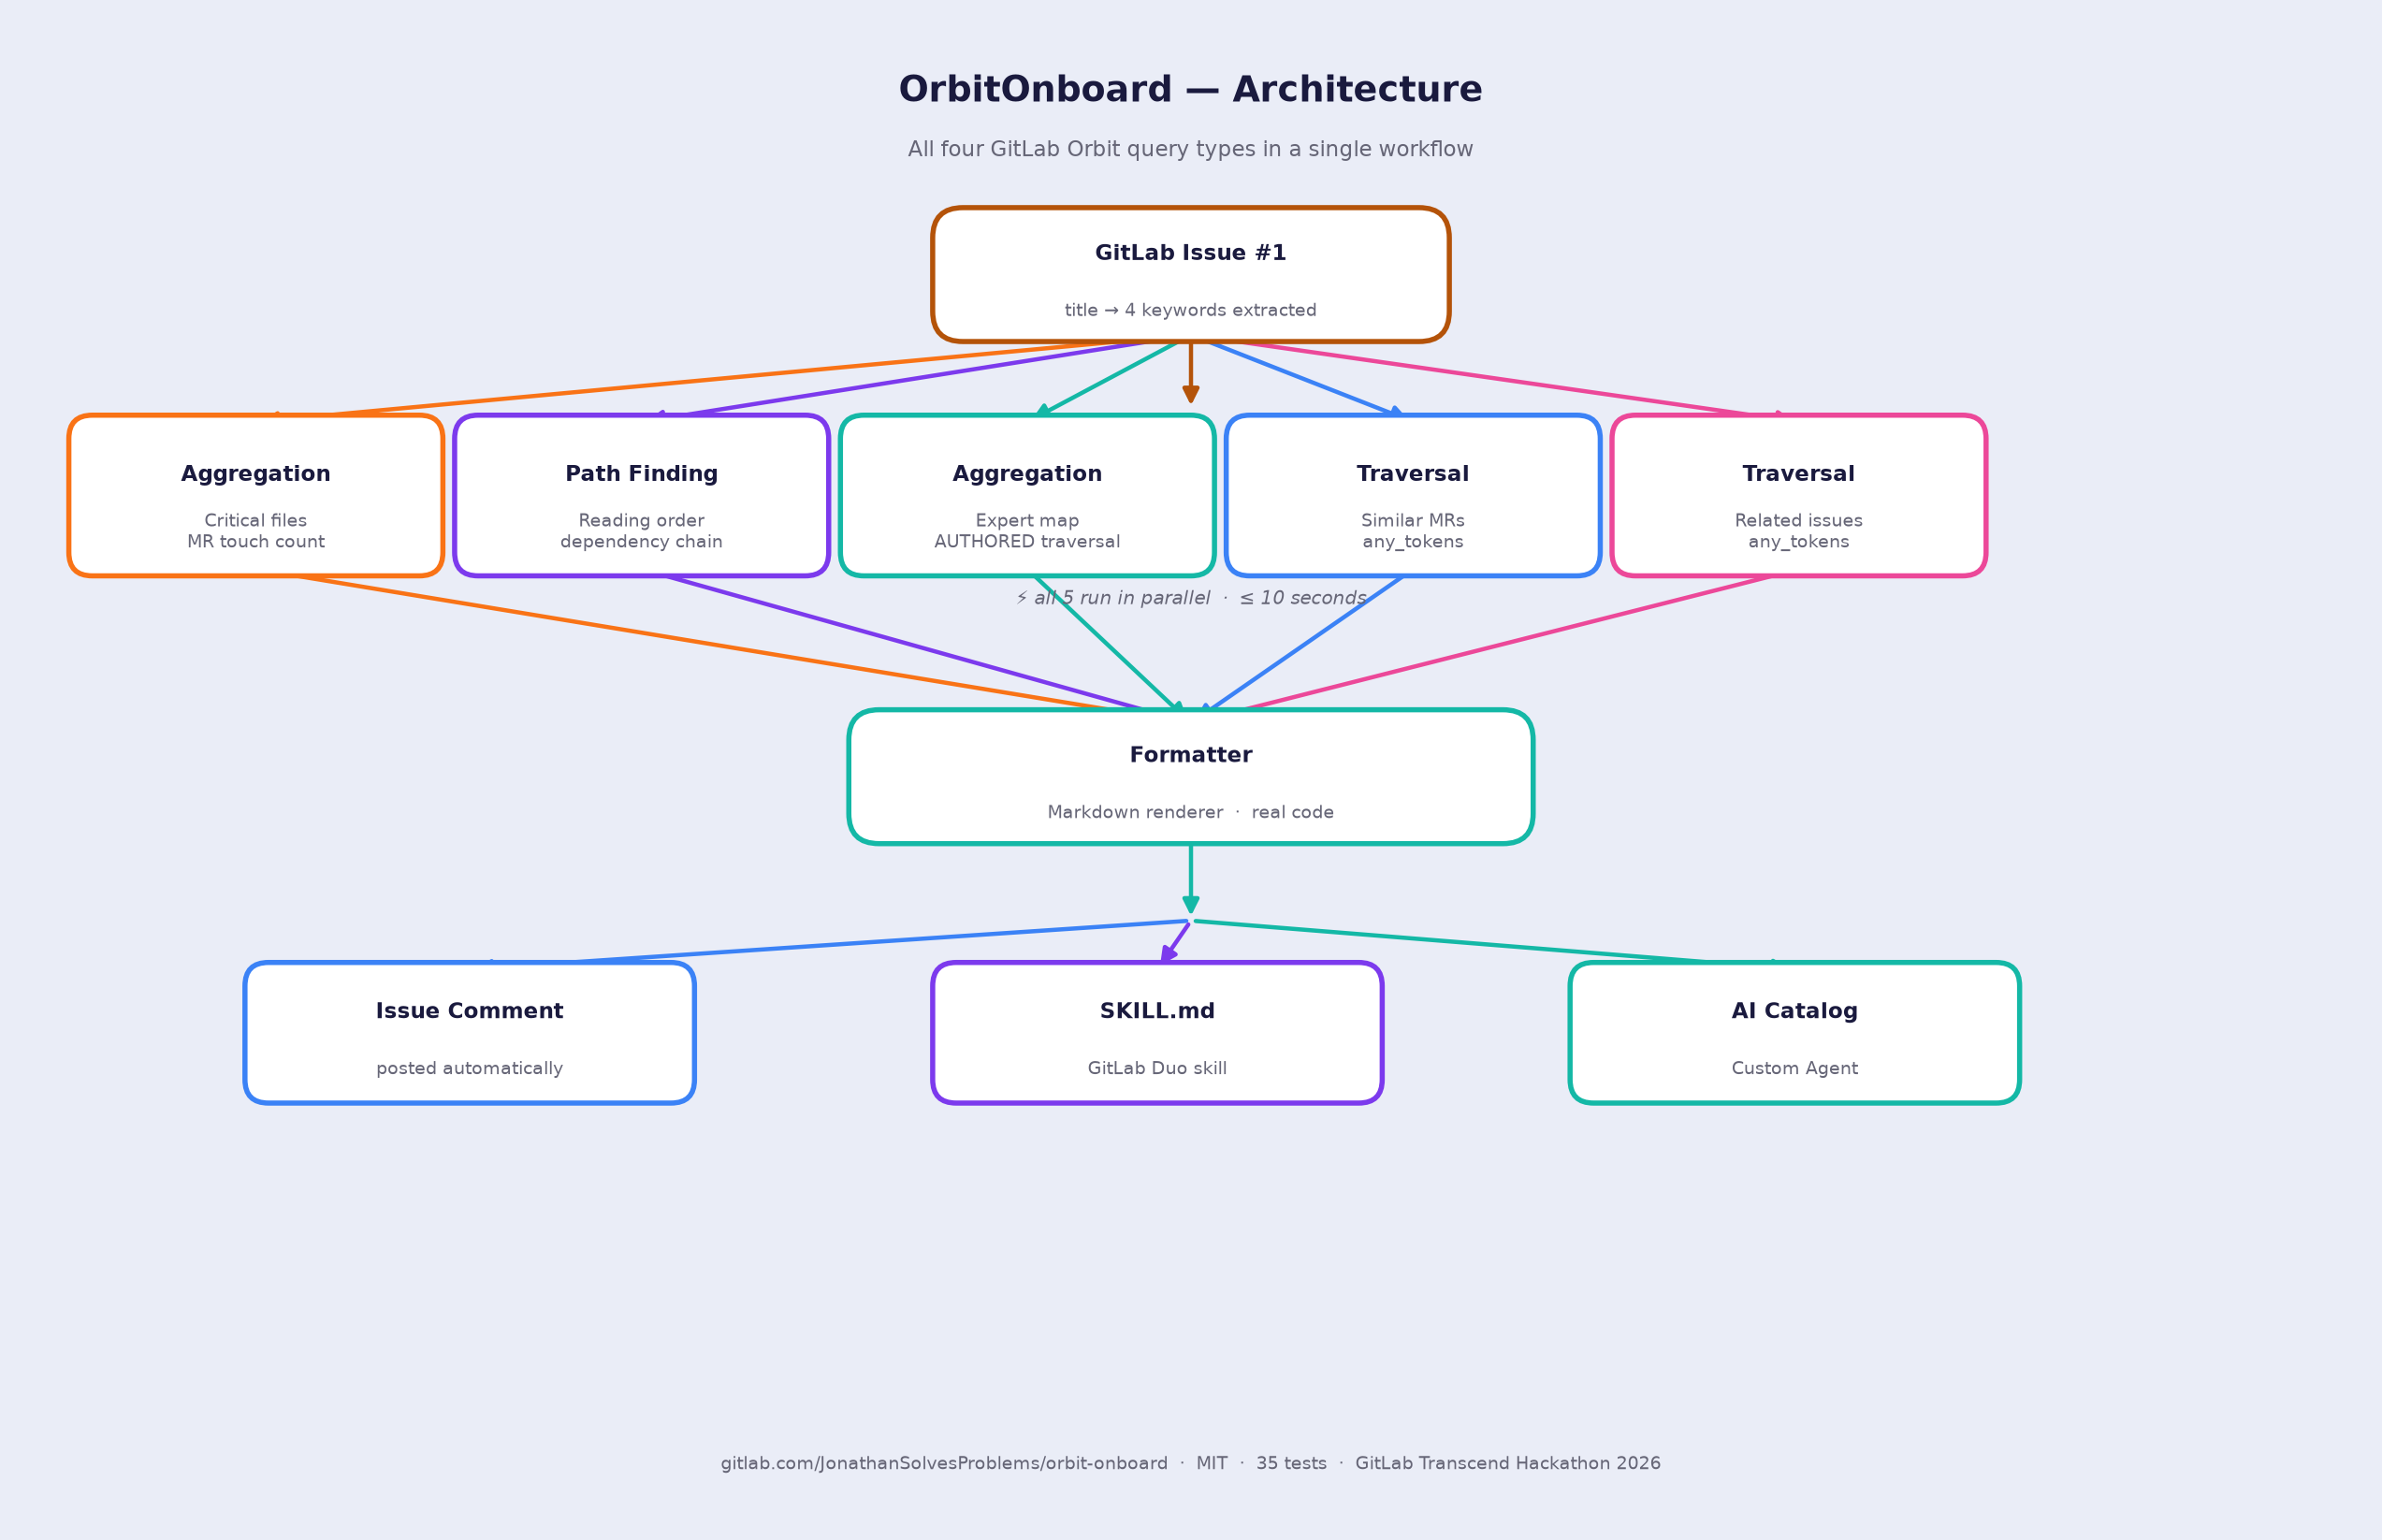
OrbitOnboard: I Used All Four GitLab Orbit Query Types to Generate a Contributor Starter Kit in 10 Seconds

Half of new contributors abandon their first attempt to contribute to an unfamiliar codebase. Not because the problem is too hard, but because the map doesn't exist. OrbitOnboard generates that map by exercising all four Orbit query types in one coordinated workflow: critical files, reading order, expert map, similar past MRs, related open issues, posted directly as an issue comment.

GitLab OrbitKnowledge GraphDeveloper Experience